Immagine
Seedream 5.0 Pro Edit Varianti: 2
a partire da 0,068 $
68 crediti API
Nessuna corrispondenza. Prova “video”, “FLUX” o “webhooks”.
Caricamento dei modelli…
bytedance/seedream/v5/pro/text-to-image
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/bytedance/seedream/v5/pro/text-to-image?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit'\''s white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65."
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/bytedance/seedream/v5/pro/text-to-image?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65."
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65.",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/bytedance/seedream/v5/pro/text-to-image", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"])# 1. Connect once (Claude Code; Cursor, VS Code, Claude Desktop: https://doitong.com/it/developers/docs/mcp)
claude mcp add --transport http doitong-models https://api.doitong.com/v1/mcp \
--header "Authorization: Bearer $DOITONG_API_KEY"
# 2. Your agent calls the "run" tool with:
{
"model_id": "bytedance/seedream/v5/pro/text-to-image",
"input": {
"prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65."
}
}Chiama il modello Seedream 5.0 Pro Text to Image (bytedance/seedream/v5/pro/text-to-image) tramite Doitong API. Documentazione per gli agenti: https://doitong.com/it/developers/models/bytedance/seedream/v5/pro/text-to-image.md
POST https://api.doitong.com/v1/run/bytedance/seedream/v5/pro/text-to-image?wait=20
Authorization: Bearer $DOITONG_API_KEY
Content-Type: application/json
{
"prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65."
}
Se lo stato della risposta è "queued" o "running", interroga GET https://api.doitong.com/v1/requests/REQUEST_ID?wait=20 finché non diventa "succeeded"; i file si trovano in outputs[].url. POST https://api.doitong.com/v1/quote/bytedance/seedream/v5/pro/text-to-image con lo stesso body restituisce il prezzo esatto prima dell'esecuzione.File come nell'esempio: 0,135 $ 135 crediti API i tuoi file vengono misurati prima dell'esecuzione Esegui in questa pagina
La tua nuova chiave API. Viene mostrata solo ora ed è già presente nel codice e nel campo della chiave API qui sotto. Mantienila segreta: non inserirla mai nel codice eseguito in un browser.
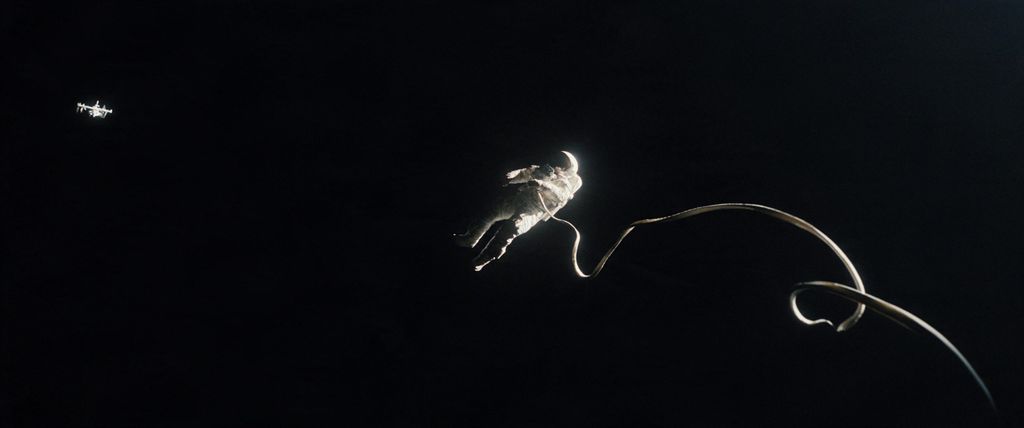
PromptHard sci-fi cinematic film still, "AIRLOCK" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65.
I controlli vengono generati dallo schema del modello. Il codice e il prezzo si aggiornano mentre li modifichi.
/run/bytedance/seedream/v5/pro/text-to-image?wait=20
preventivo → 0,135 $
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/bytedance/seedream/v5/pro/text-to-image?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit'\''s white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65."
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/bytedance/seedream/v5/pro/text-to-image?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65."
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65.",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/bytedance/seedream/v5/pro/text-to-image", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"]){
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "run",
"arguments": {
"model_id": "bytedance/seedream/v5/pro/text-to-image",
"input": {
"prompt": "Hard sci-fi cinematic film still, \"AIRLOCK\" — SHOT 3: Wide vertiginous establishing shot. A lone astronaut in a white EVA suit tumbles slowly in zero gravity, impossibly small against the absolute black of deep space. The figure is positioned off-center, slightly diagonal — the slow rotation implied by body posture. A severed umbilical tether trails loose behind the suit, drifting in a long graceful arc. Far in the upper corner, the space station is a tiny receding white geometric speck, maybe 10 pixels of implied detail. Nothing else. Pure black void filling 90% of the frame. The astronaut is the only warm element — the suit's white catching the single hard solar key light, one side blazing white-silver, the shadow side absolute black. No stars. No nebula. Just black. Cold desaturated palette, the suit slightly yellowed-ivory against void. Anamorphic 2.39:1 letterboxed, extreme negative space. 35mm film grain. The scale creates overwhelming existential dread. Hyper-real photographic detail. Shot on ARRI Alexa 65."
},
"wait_seconds": 20
}
}
}La tua chiave rimane in questo browser: viene inviata solo al Doitong API e salvata in localStorage solo se selezioni Ricorda. Ottieni una chiave API
Lavori pubblici creati con Seedream 5.0 Pro dalla community di Doitong. Riutilizza un prompt con un clic.
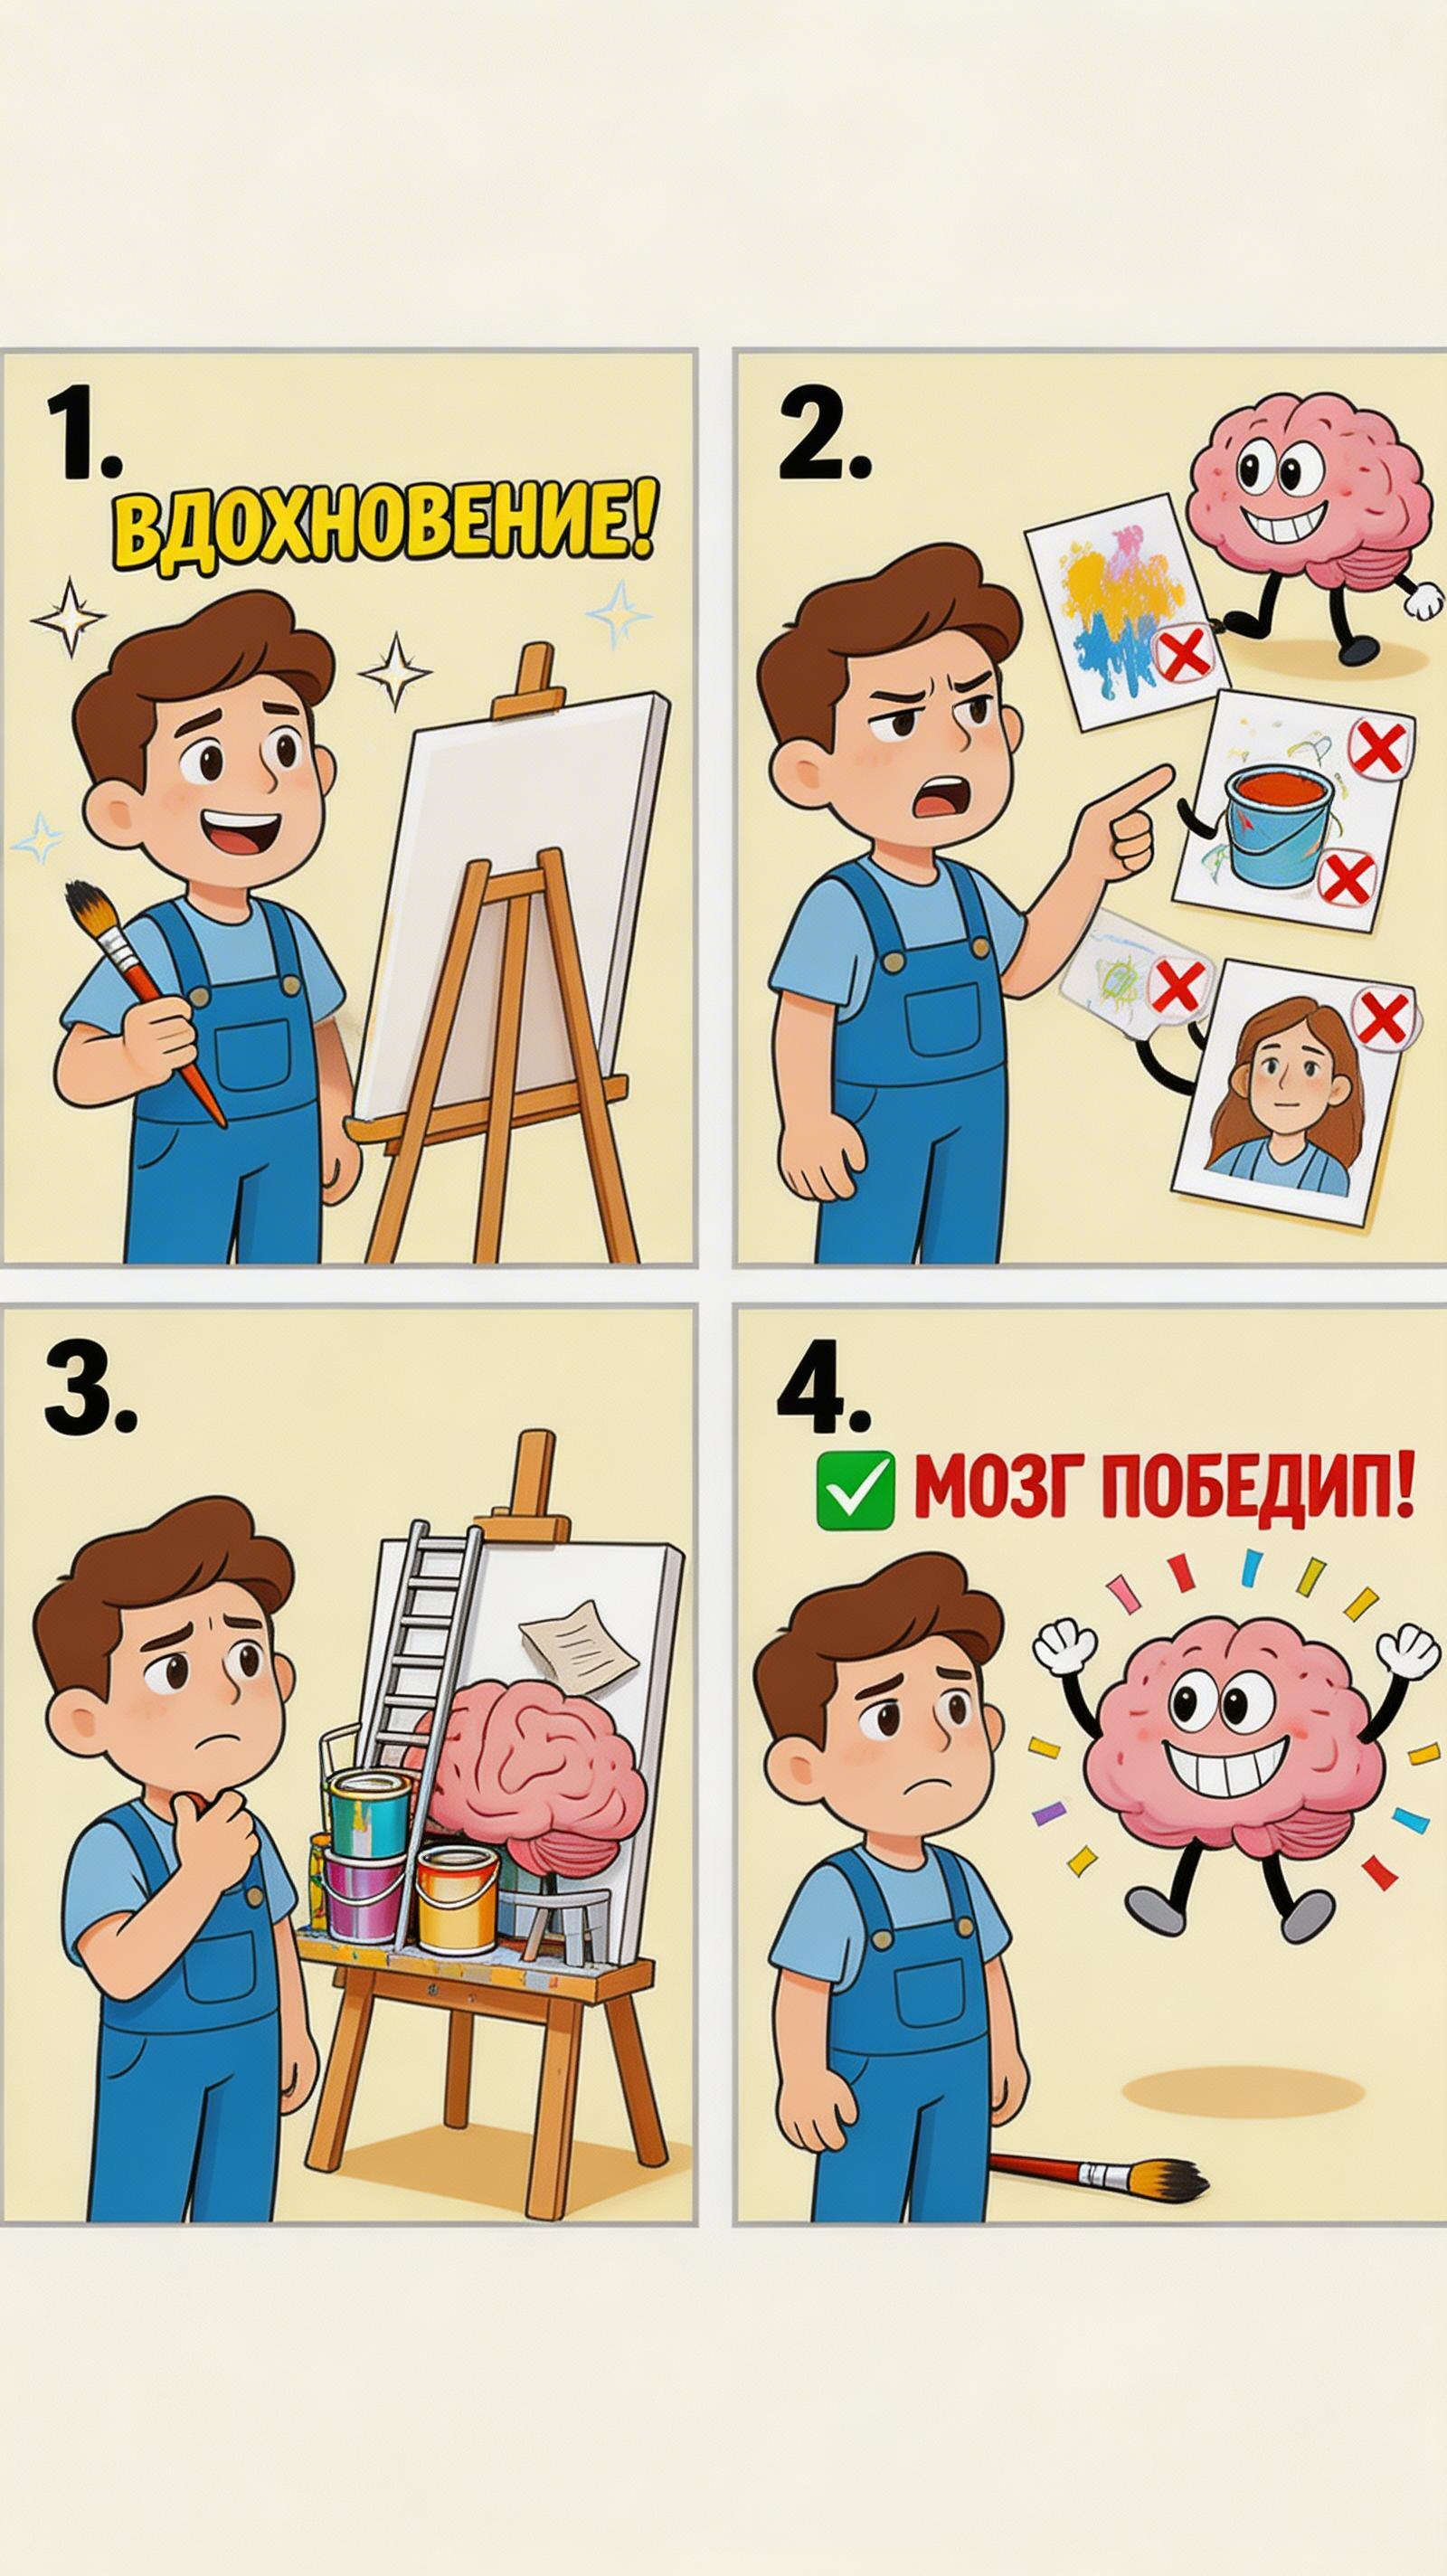
Создайте 20-секундный анимационный ролик в ярком, мультяшном стиле для Instagram. Сюжет: человек с вдохновением собирается начать что-то новое (например, рисовать на холсте). Внезапно появляется его Мозг в виде забавного персонажа, который начинает активно мешать: показывает смешные картинки...

Art style: Cinematic Realistic. A hand gently reaching out to a wooden bookshelf filled with beautifully bound books. The fingers softly touch the spines. Warm, golden hour lighting. No faces. ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ FINAL STYLE ENFORCEMENT (this is the authoritative rendering...

Art style: Studio Ghibli animation style, lush forest and waterfall setting, warm sunlight filtering through trees, cozy wooden treehouse, high detail, 4K.. Studio Ghibli animation style. Close-up of Elara's hands carefully picking one of the glowing mushrooms and placing it into a small woven...
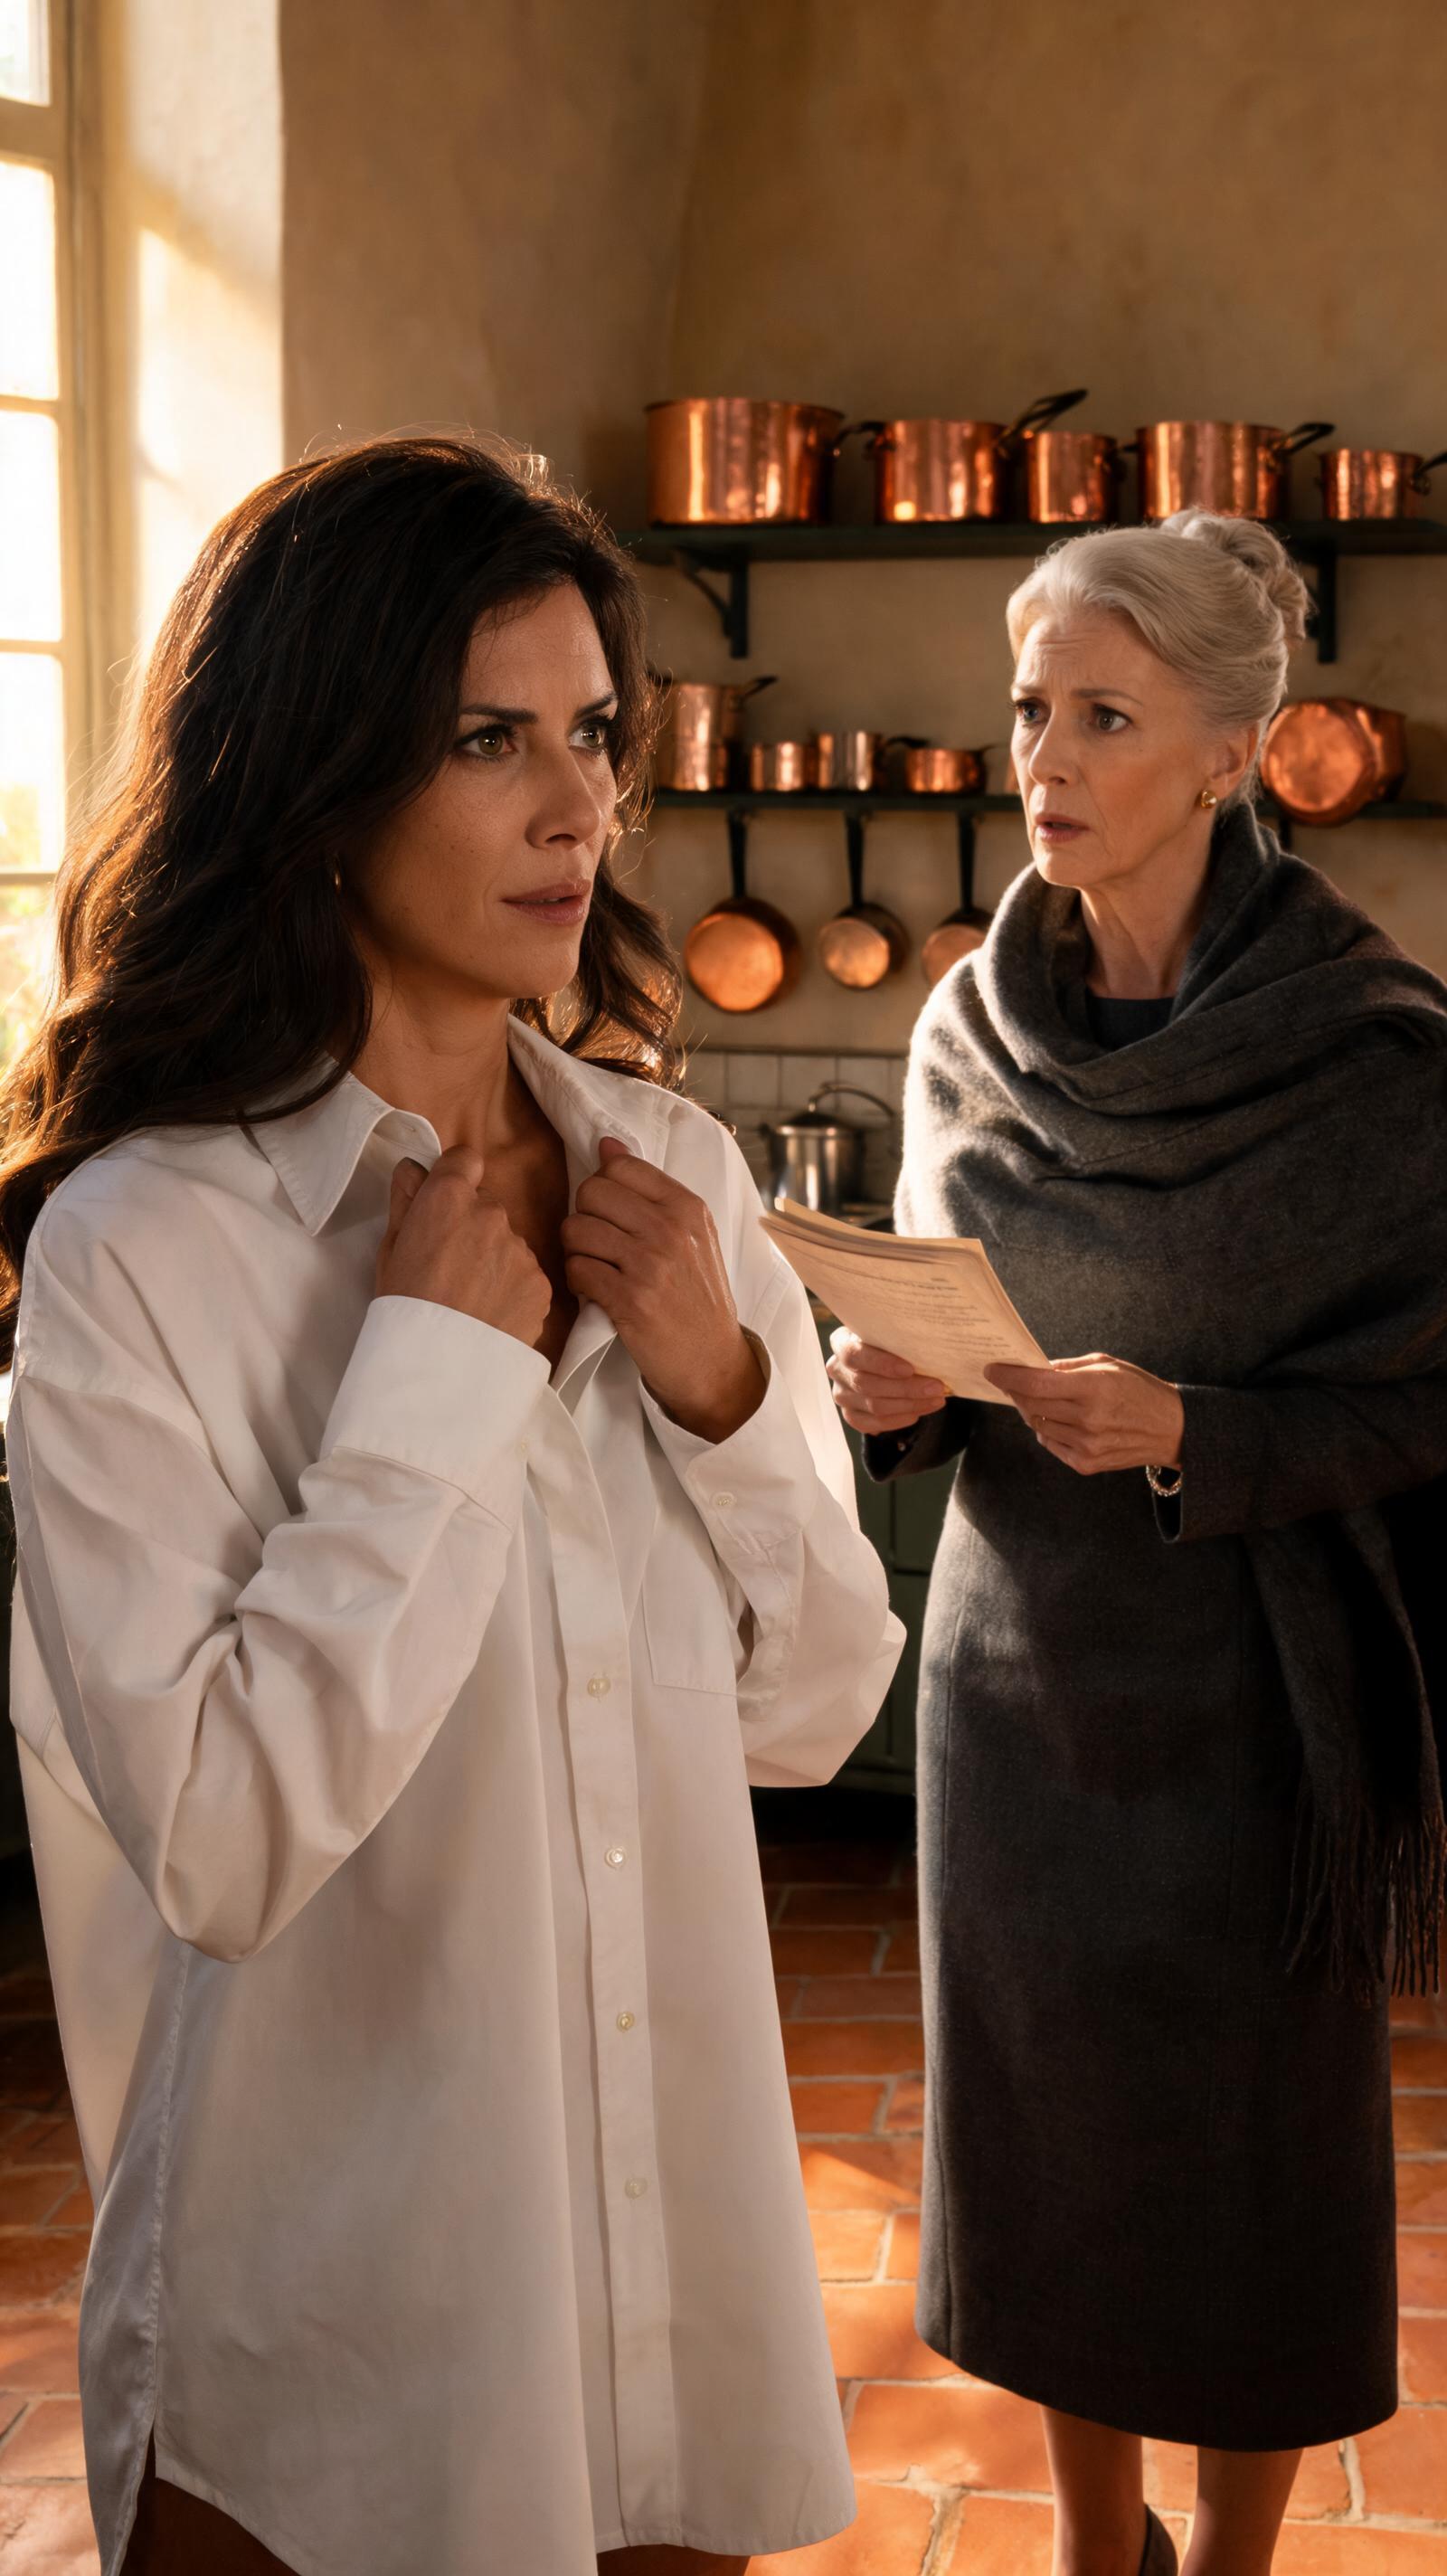
Art style: Cinematic Realistic. Maya standing in the near foreground; Eleanora standing further back in the frame. Three feet of terracotta floor between them. Maya is standing on terracotta floor in the near foreground in the midground. Torso in three-quarter turn to screen-right. Head in...
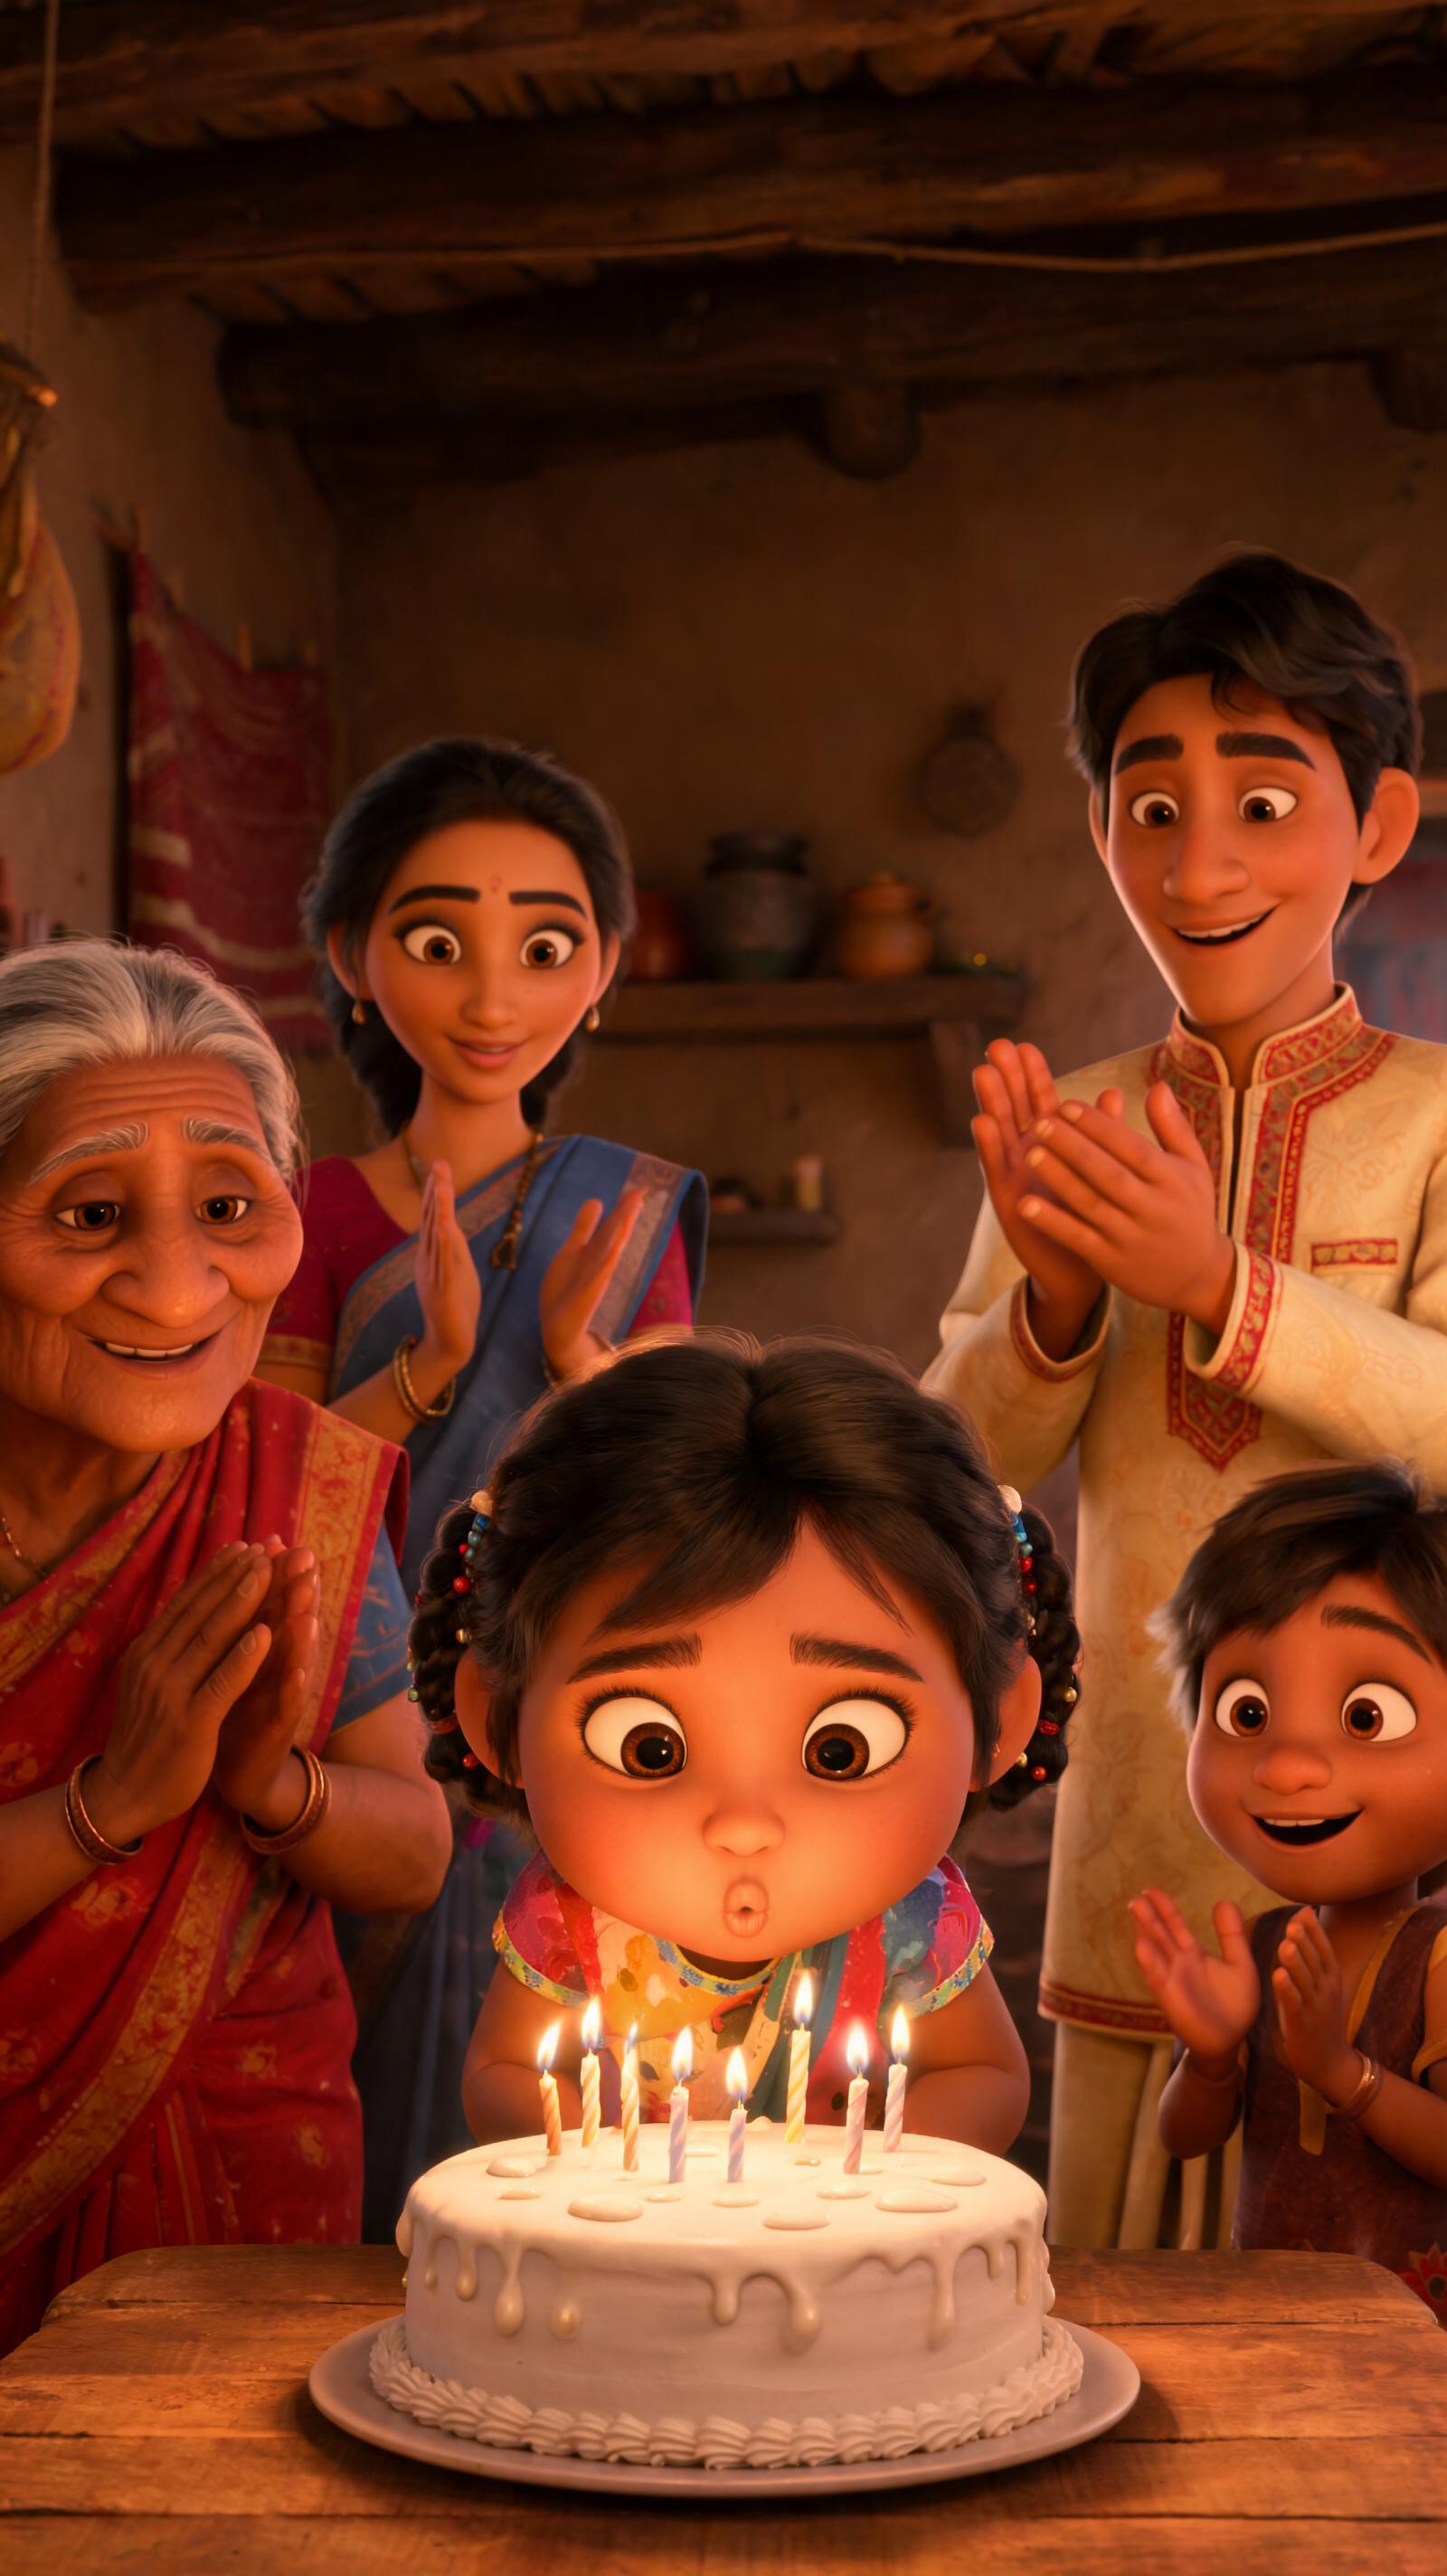
A still from a 3D animated feature film, vertical 9:16, stylised appealing characters with expressive eyes, soft warm cinematic lighting, richly detailed setting, no text, no captions. Nepal, 1993. The main character is a 3-year-old girl, seen in an ordinary modest village setting. Scene: A cake...
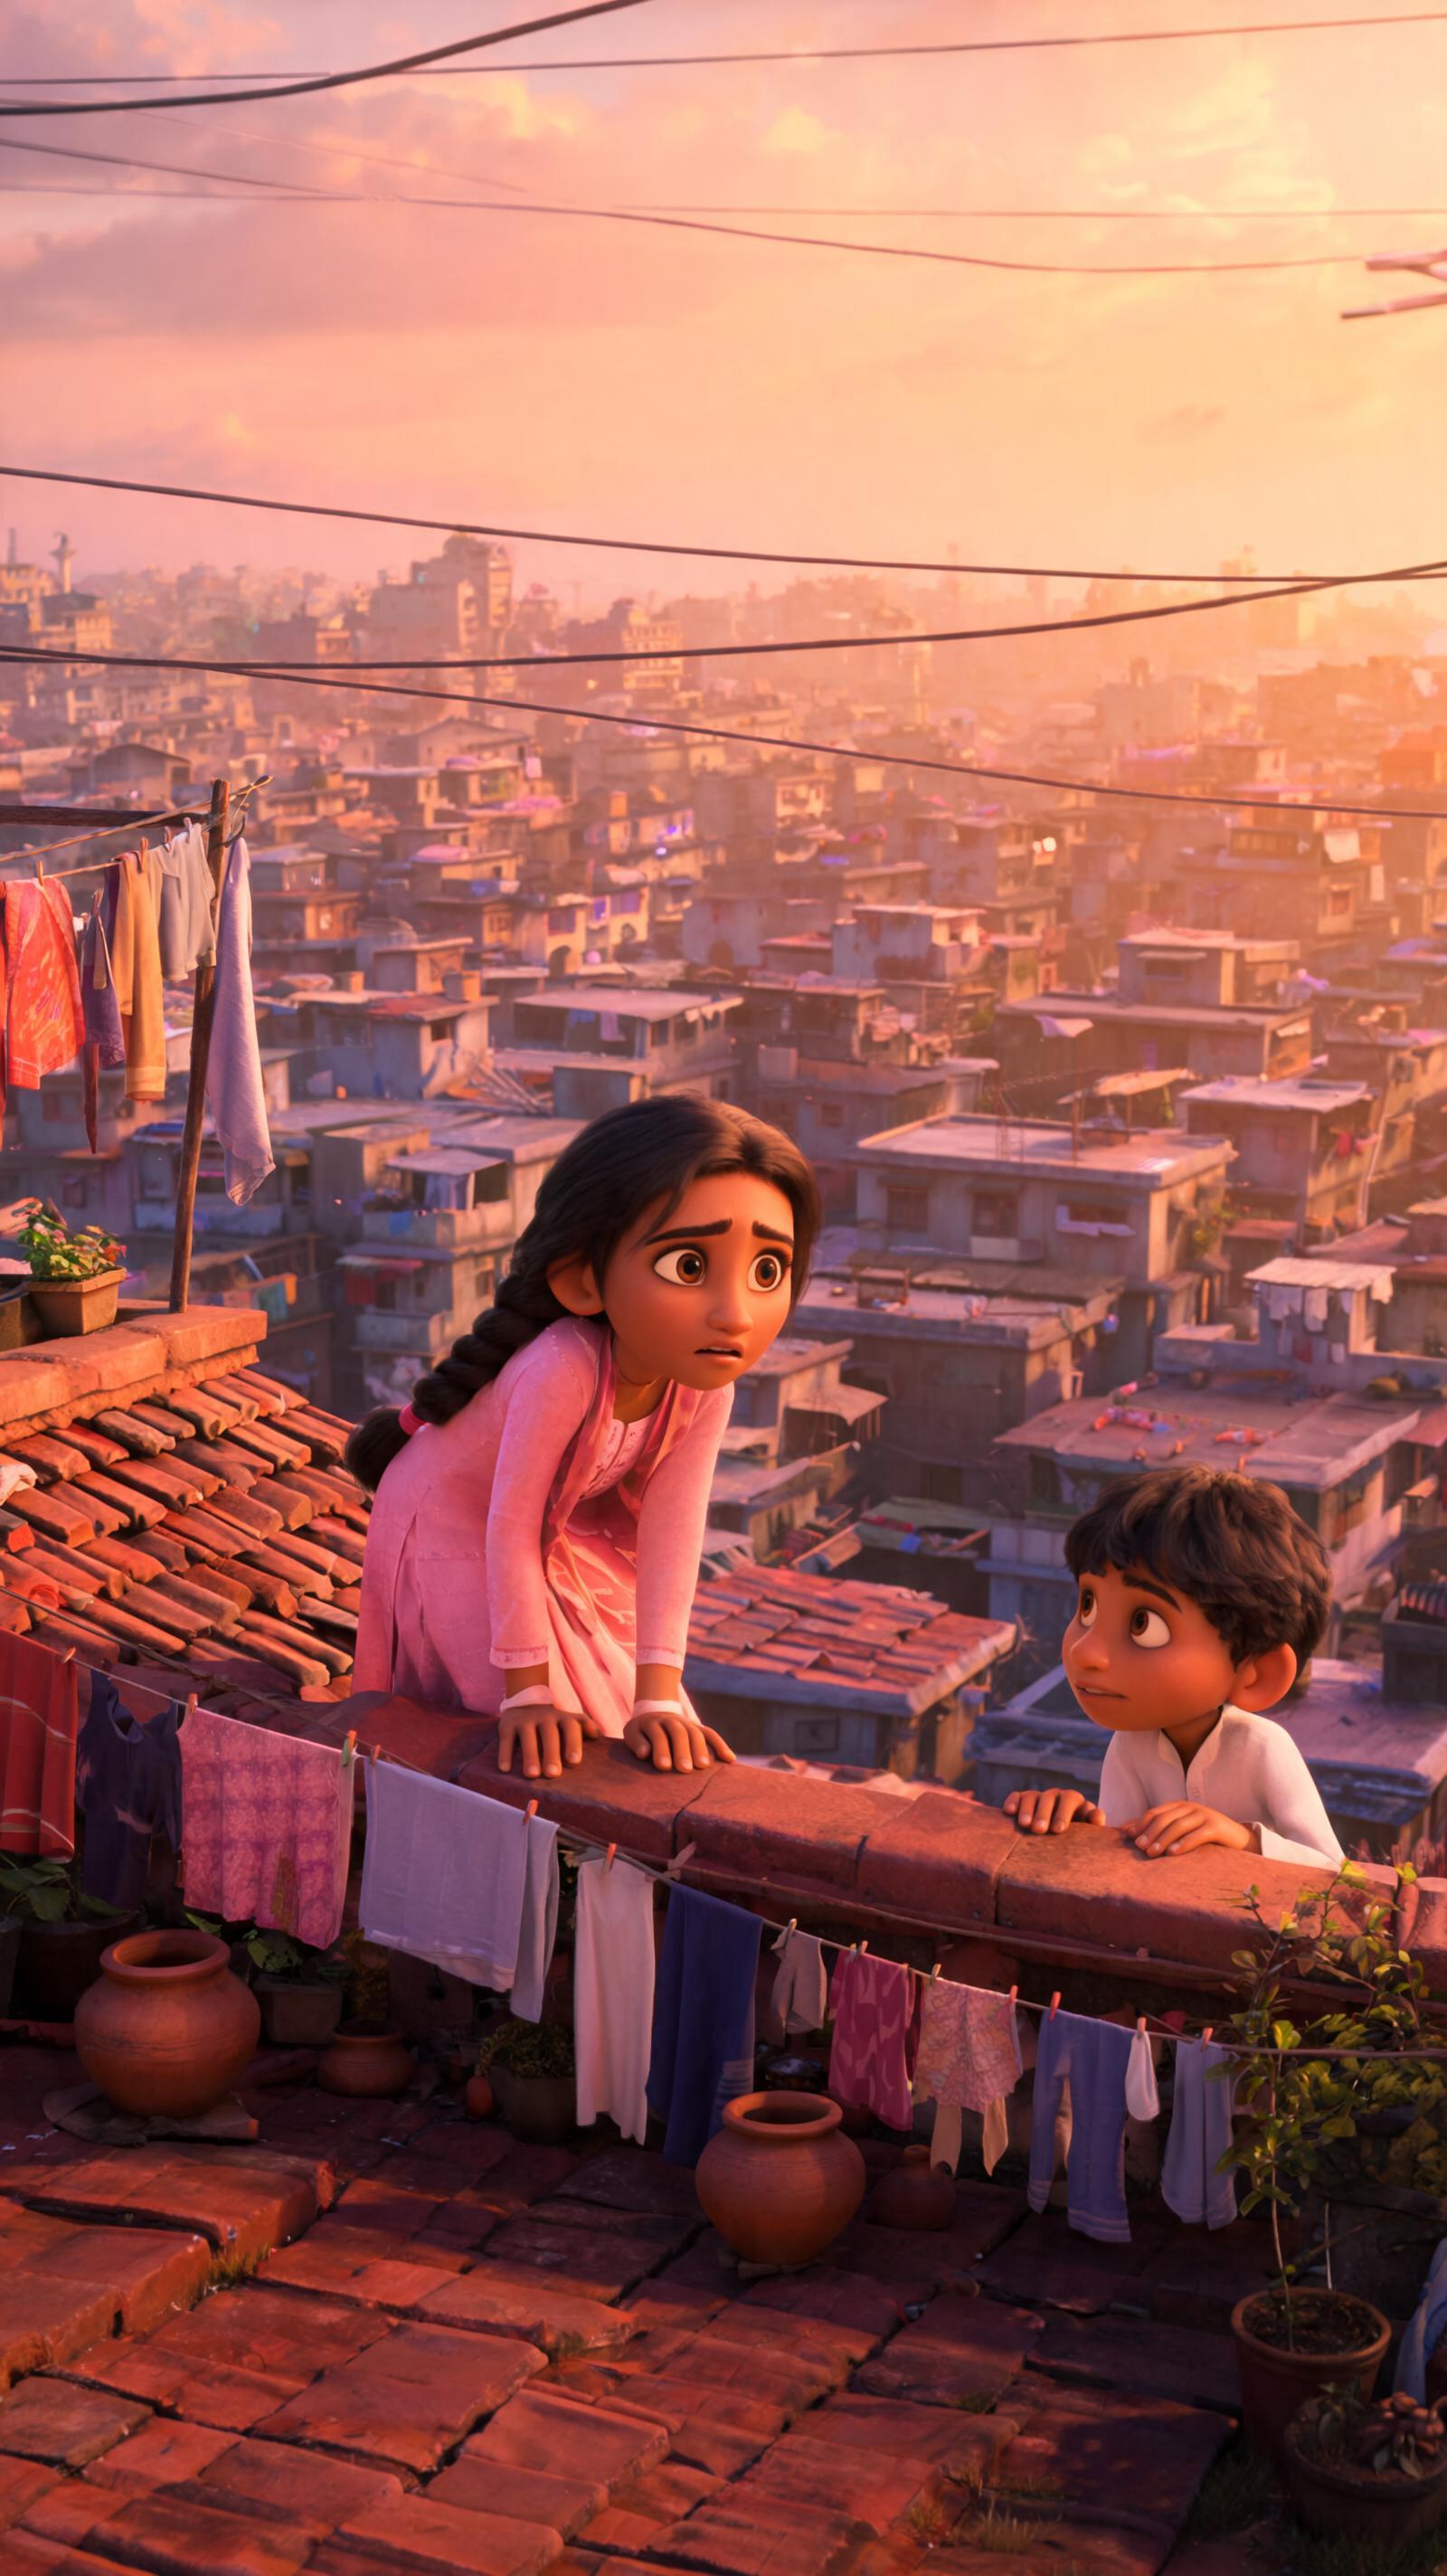
A still from a 3D animated feature film, vertical 9:16, stylised appealing characters with expressive eyes, soft warm cinematic lighting, richly detailed setting, no text, no captions. Mumbai, India, 1996. The main character is a 8-year-old girl, seen in an ordinary poor city setting. Scene: You...
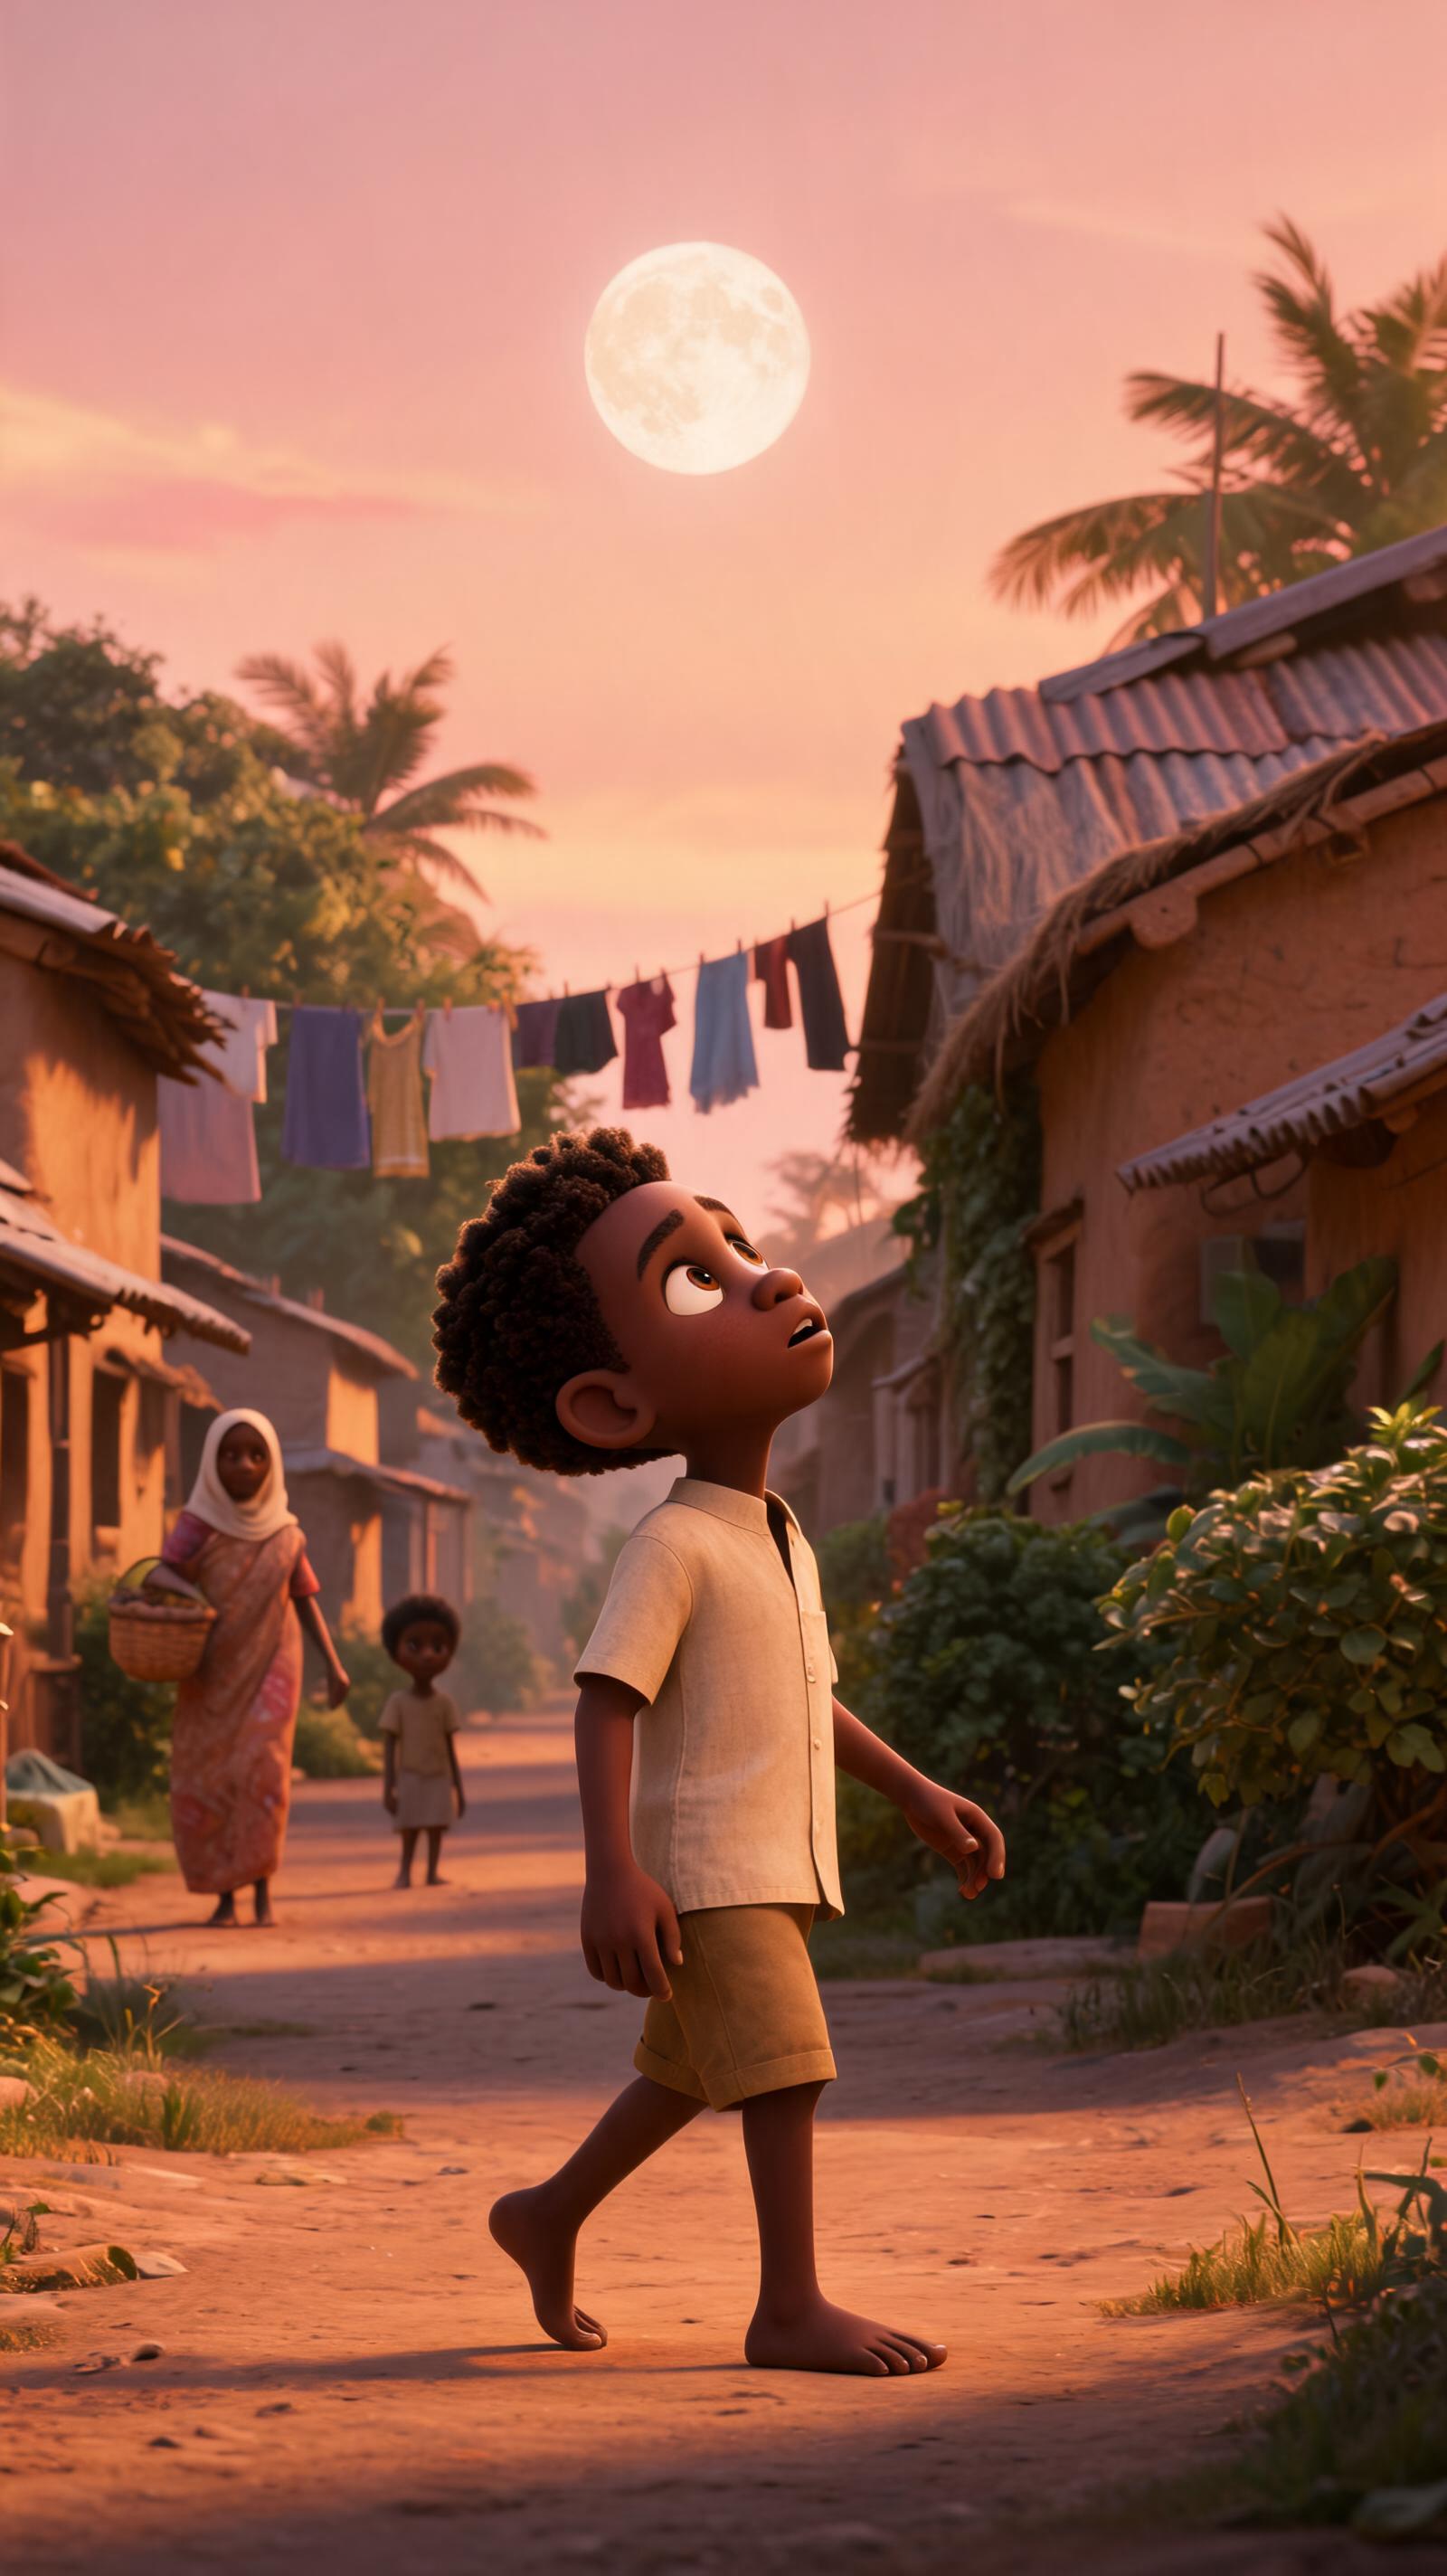
A still from a 3D animated feature film, vertical 9:16, stylised appealing characters with expressive eyes, soft warm cinematic lighting, richly detailed setting, no text, no captions. Bamenda, Cameroon, 1973. The main character is a 5-year-old boy, seen in an ordinary poor city setting. Scene:...
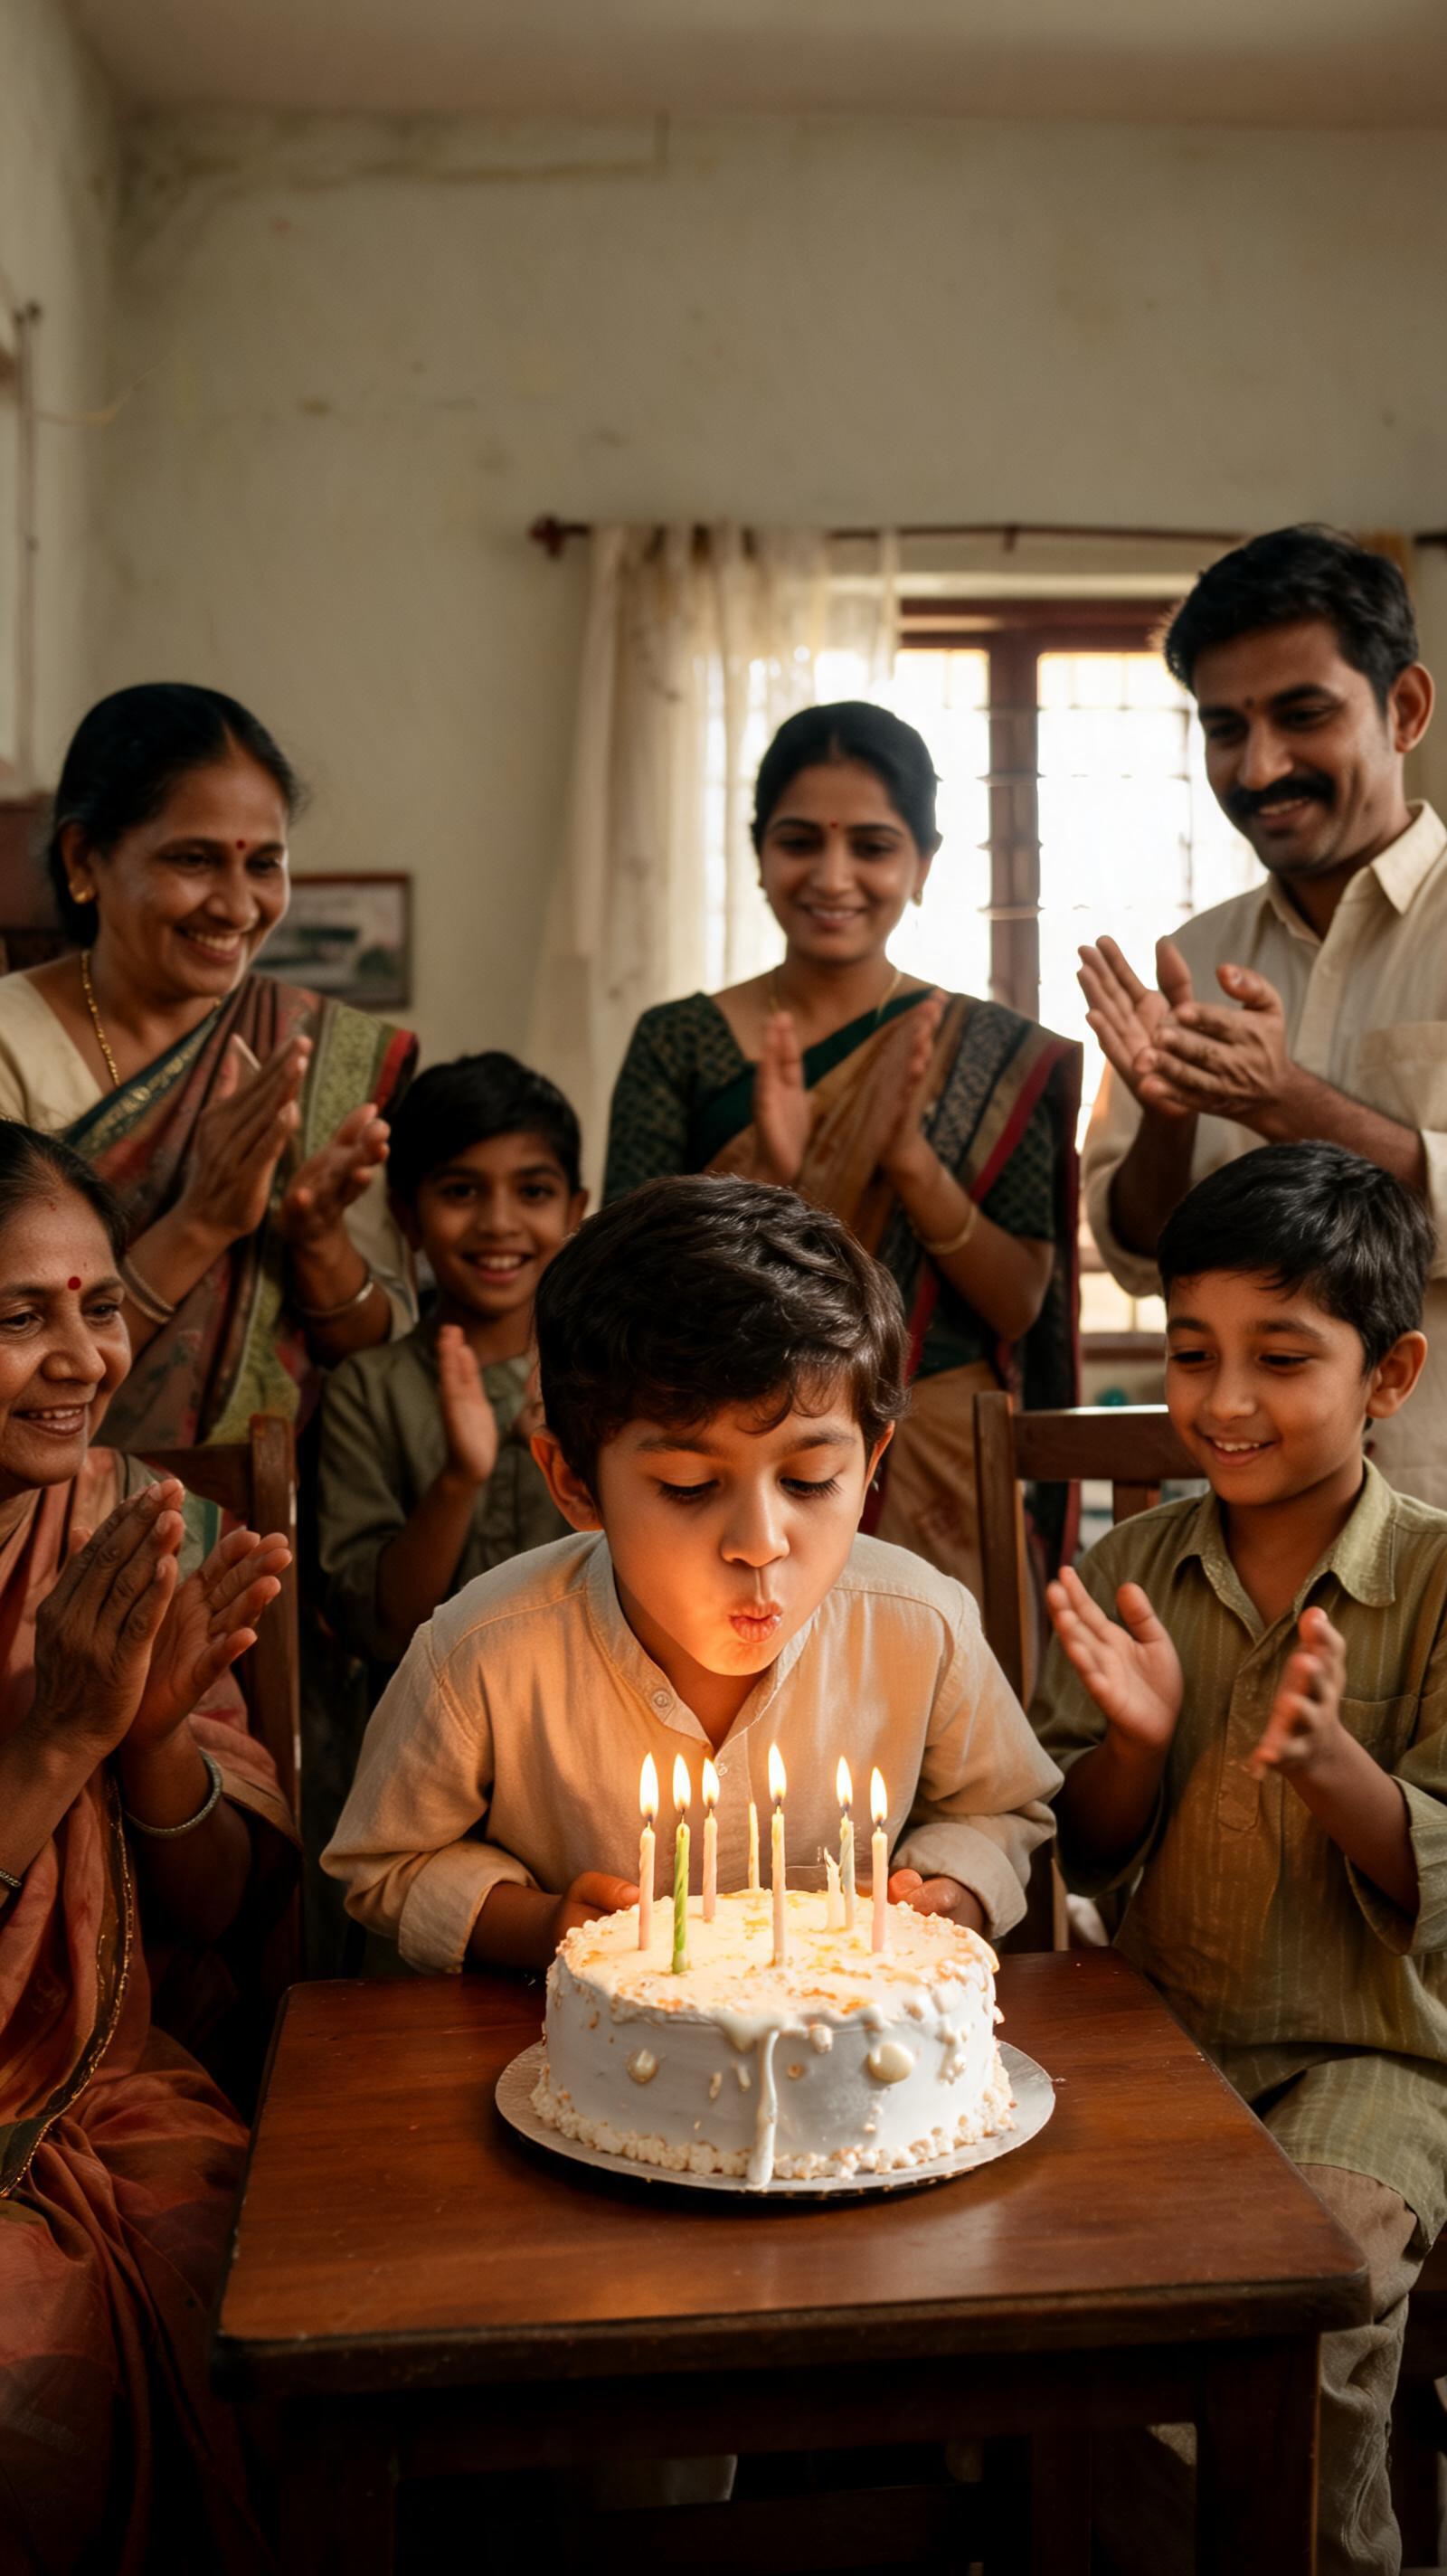
A cinematic film still, vertical 9:16, natural light, documentary realism, no text, no captions. Bengaluru, India, 1967. The main character is a 3-year-old boy, seen in an ordinary modest city setting. Scene: A cake with candles. You blow so hard that wax lands on the icing, and everyone claps...
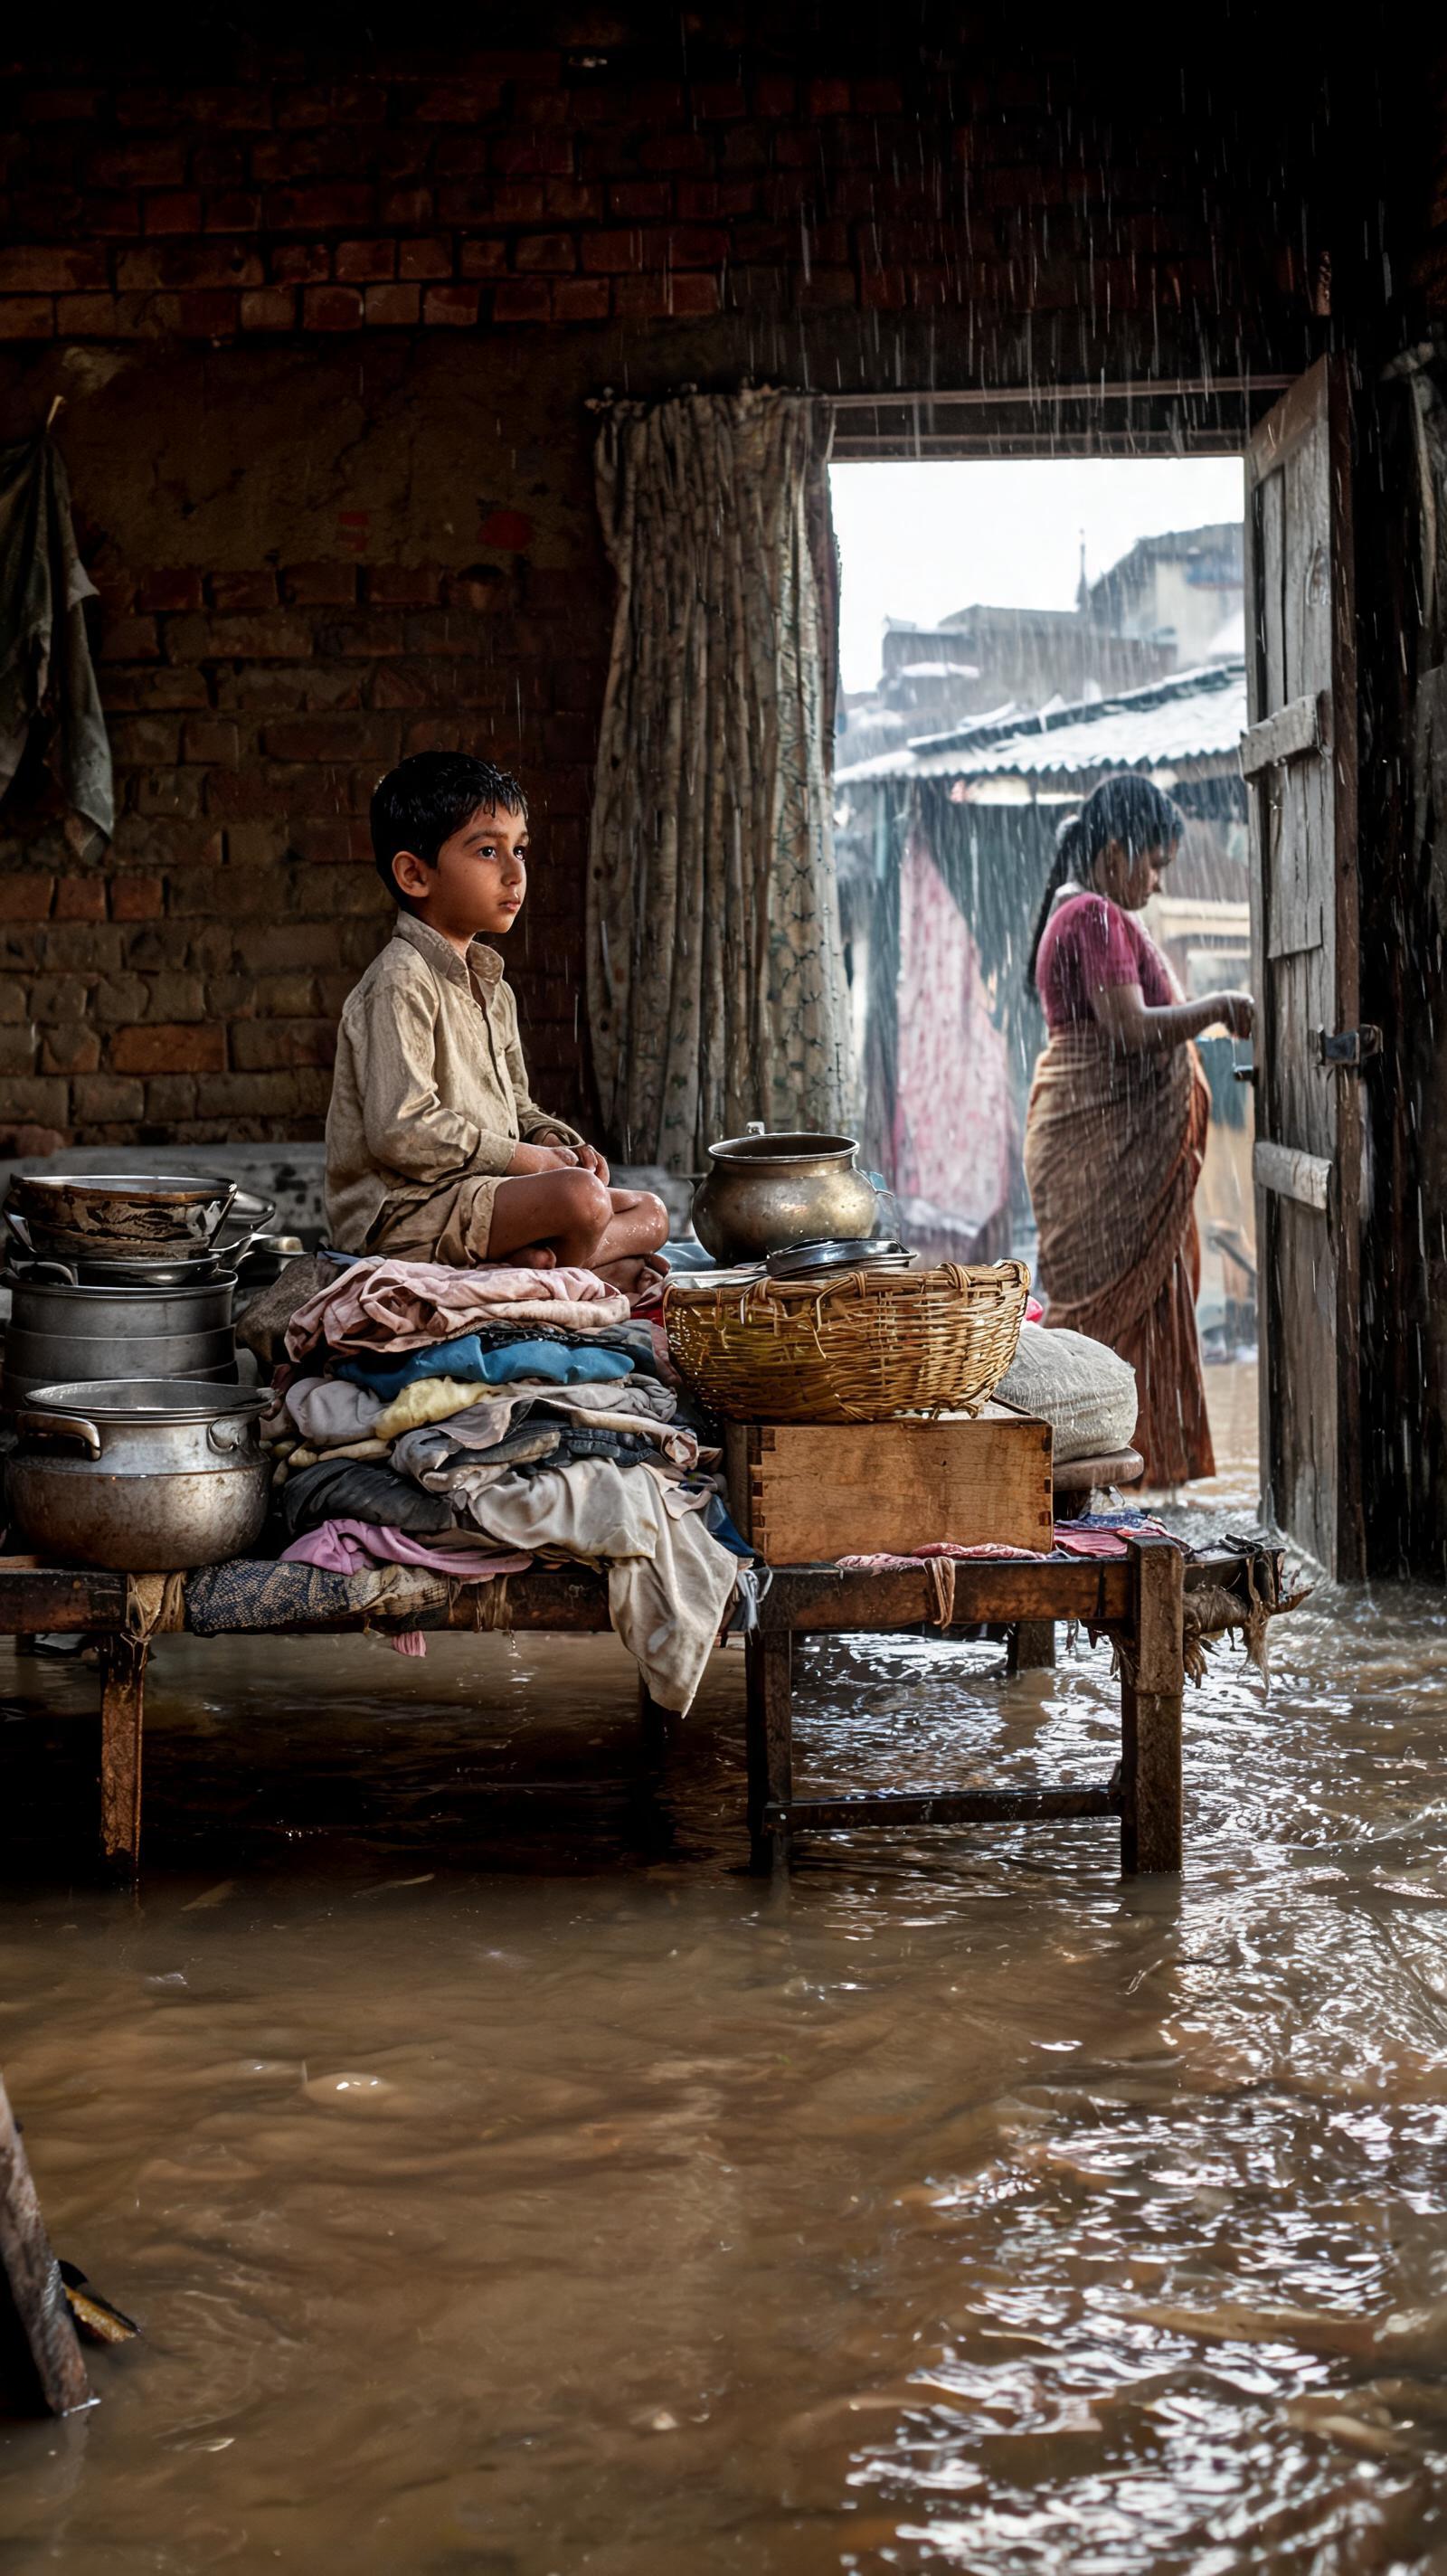
A cinematic film still, vertical 9:16, natural light, documentary realism, no text, no captions. Delhi, India, 1974. The main character is a 6-year-old boy, seen in an ordinary poor city setting. Scene: During the rains water comes into the house. Everything is lifted onto the bed, and you sit on...
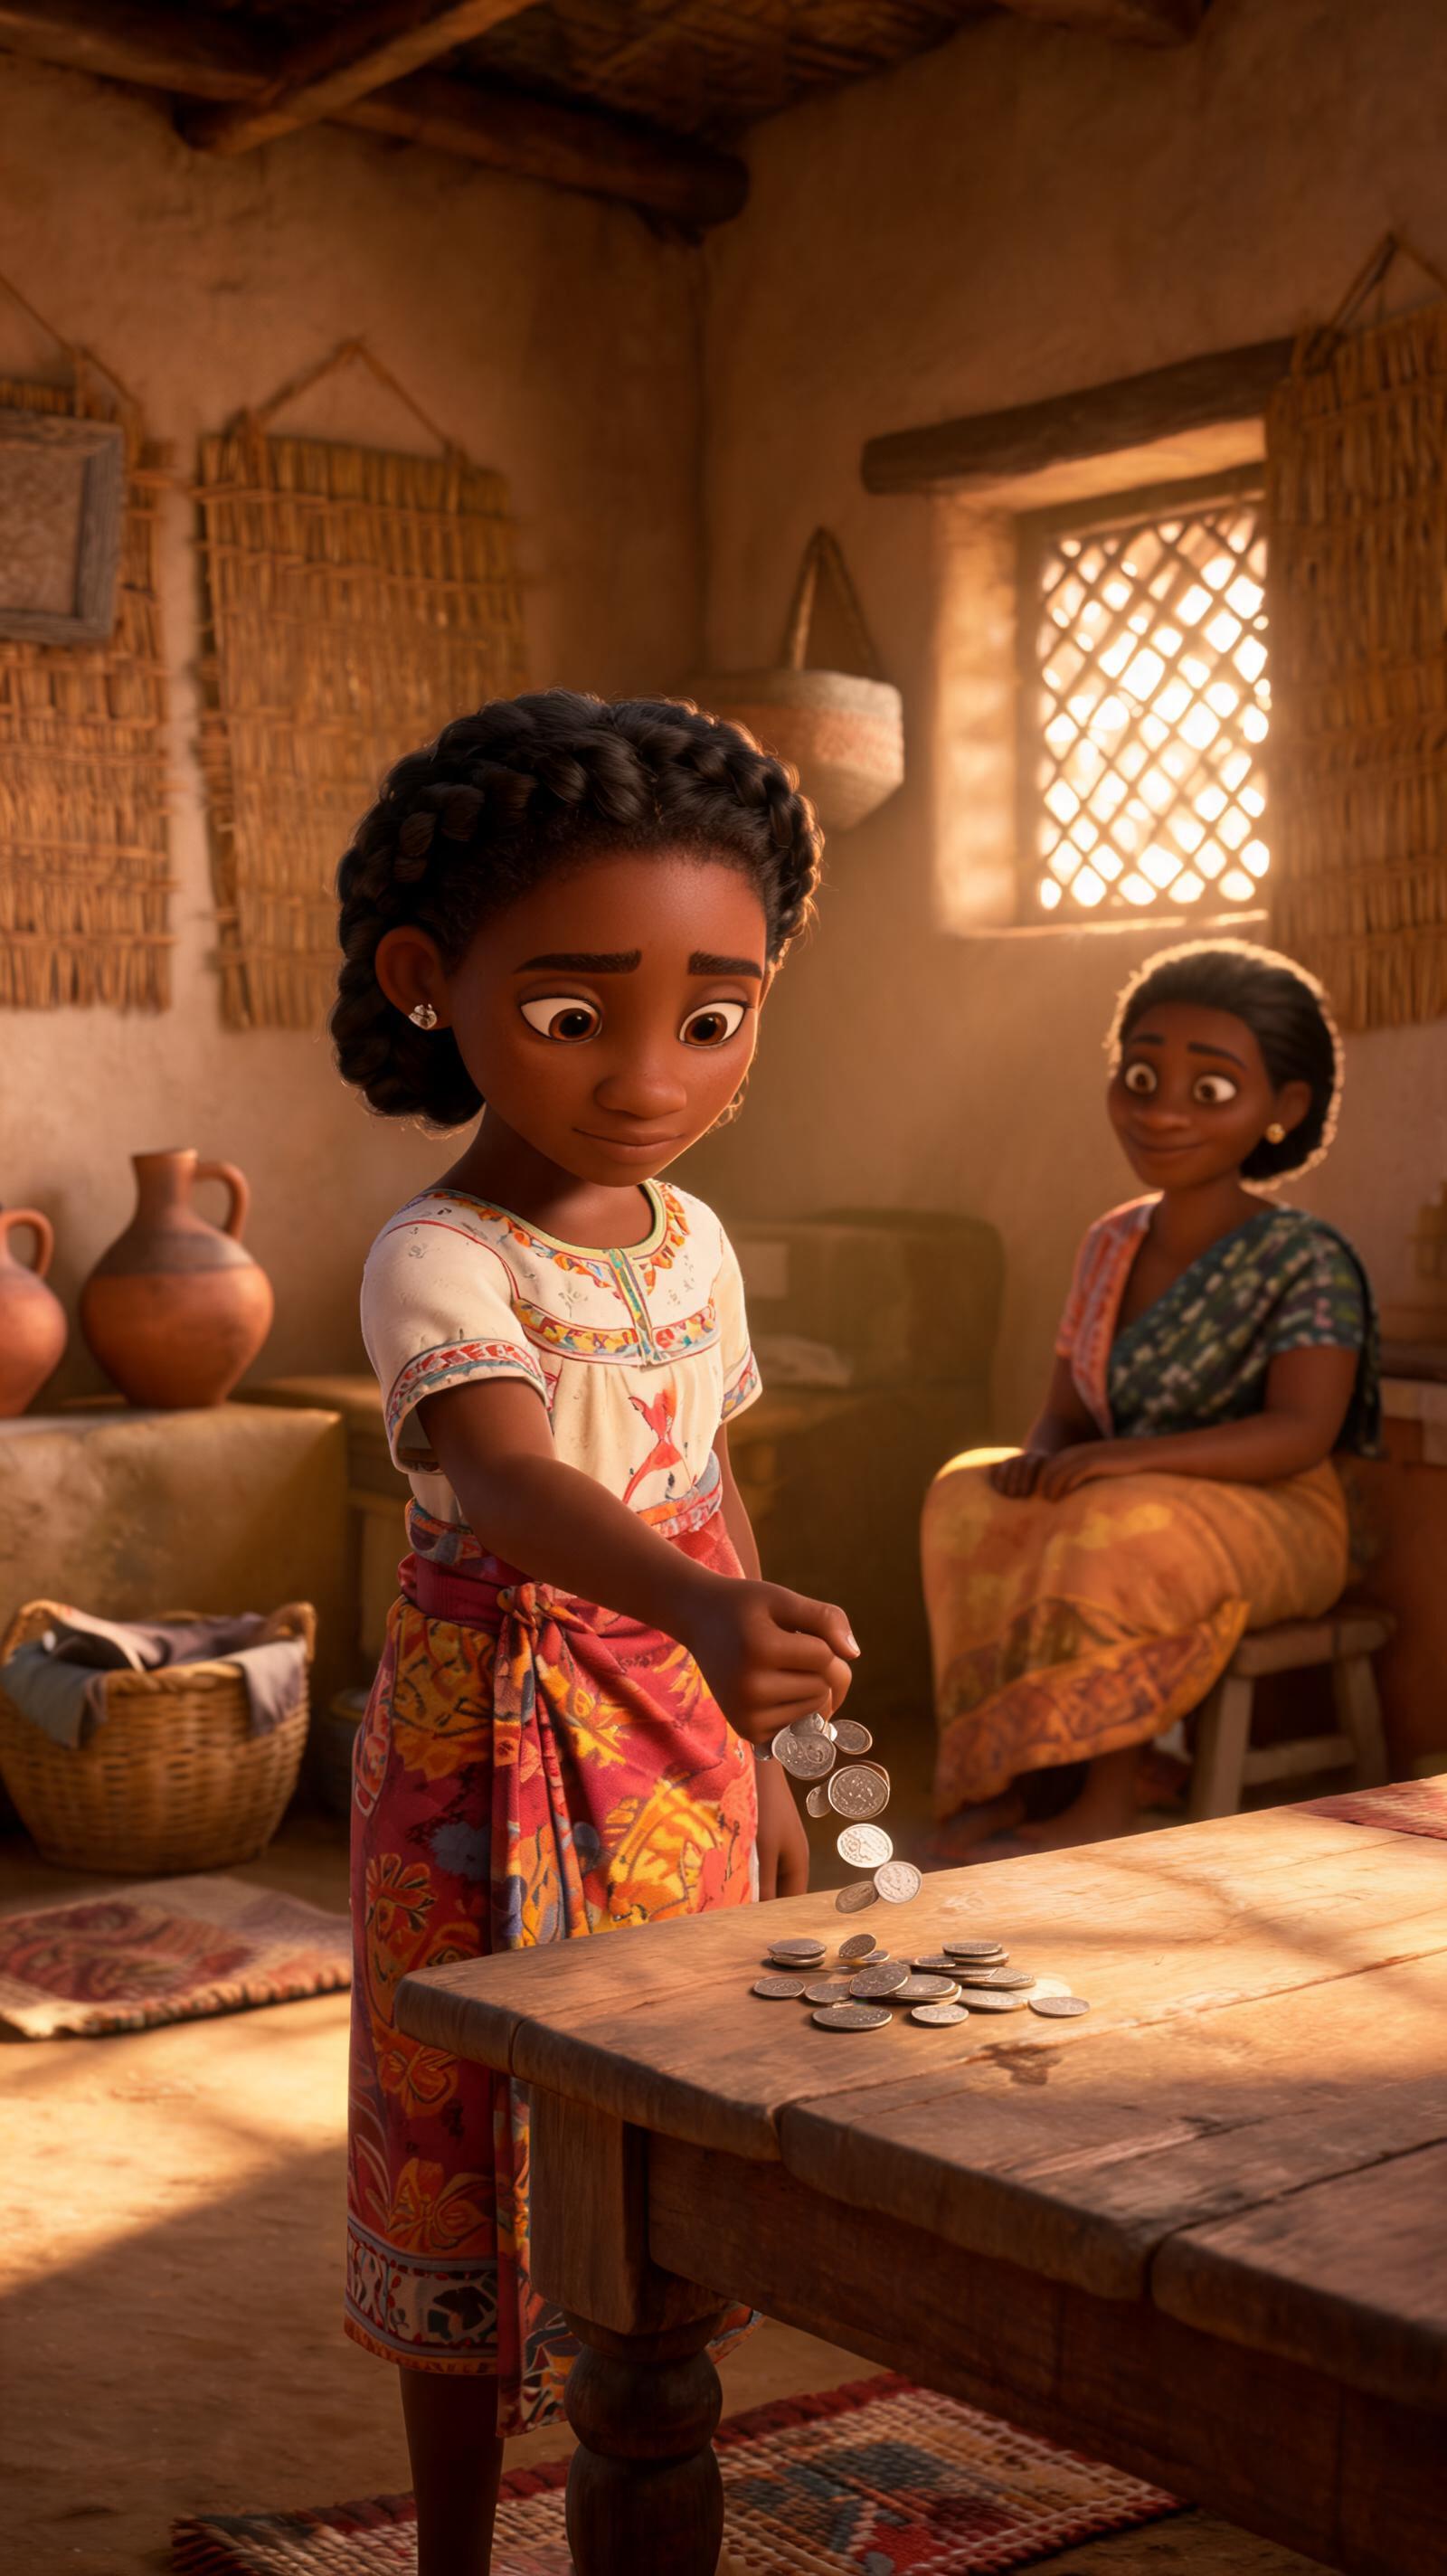
A still from a 3D animated feature film, vertical 9:16, stylised appealing characters with expressive eyes, soft warm cinematic lighting, richly detailed setting, no text, no captions. Benin City, Nigeria, 1972. The main character is a 9-year-old girl, seen in an ordinary poor city setting....
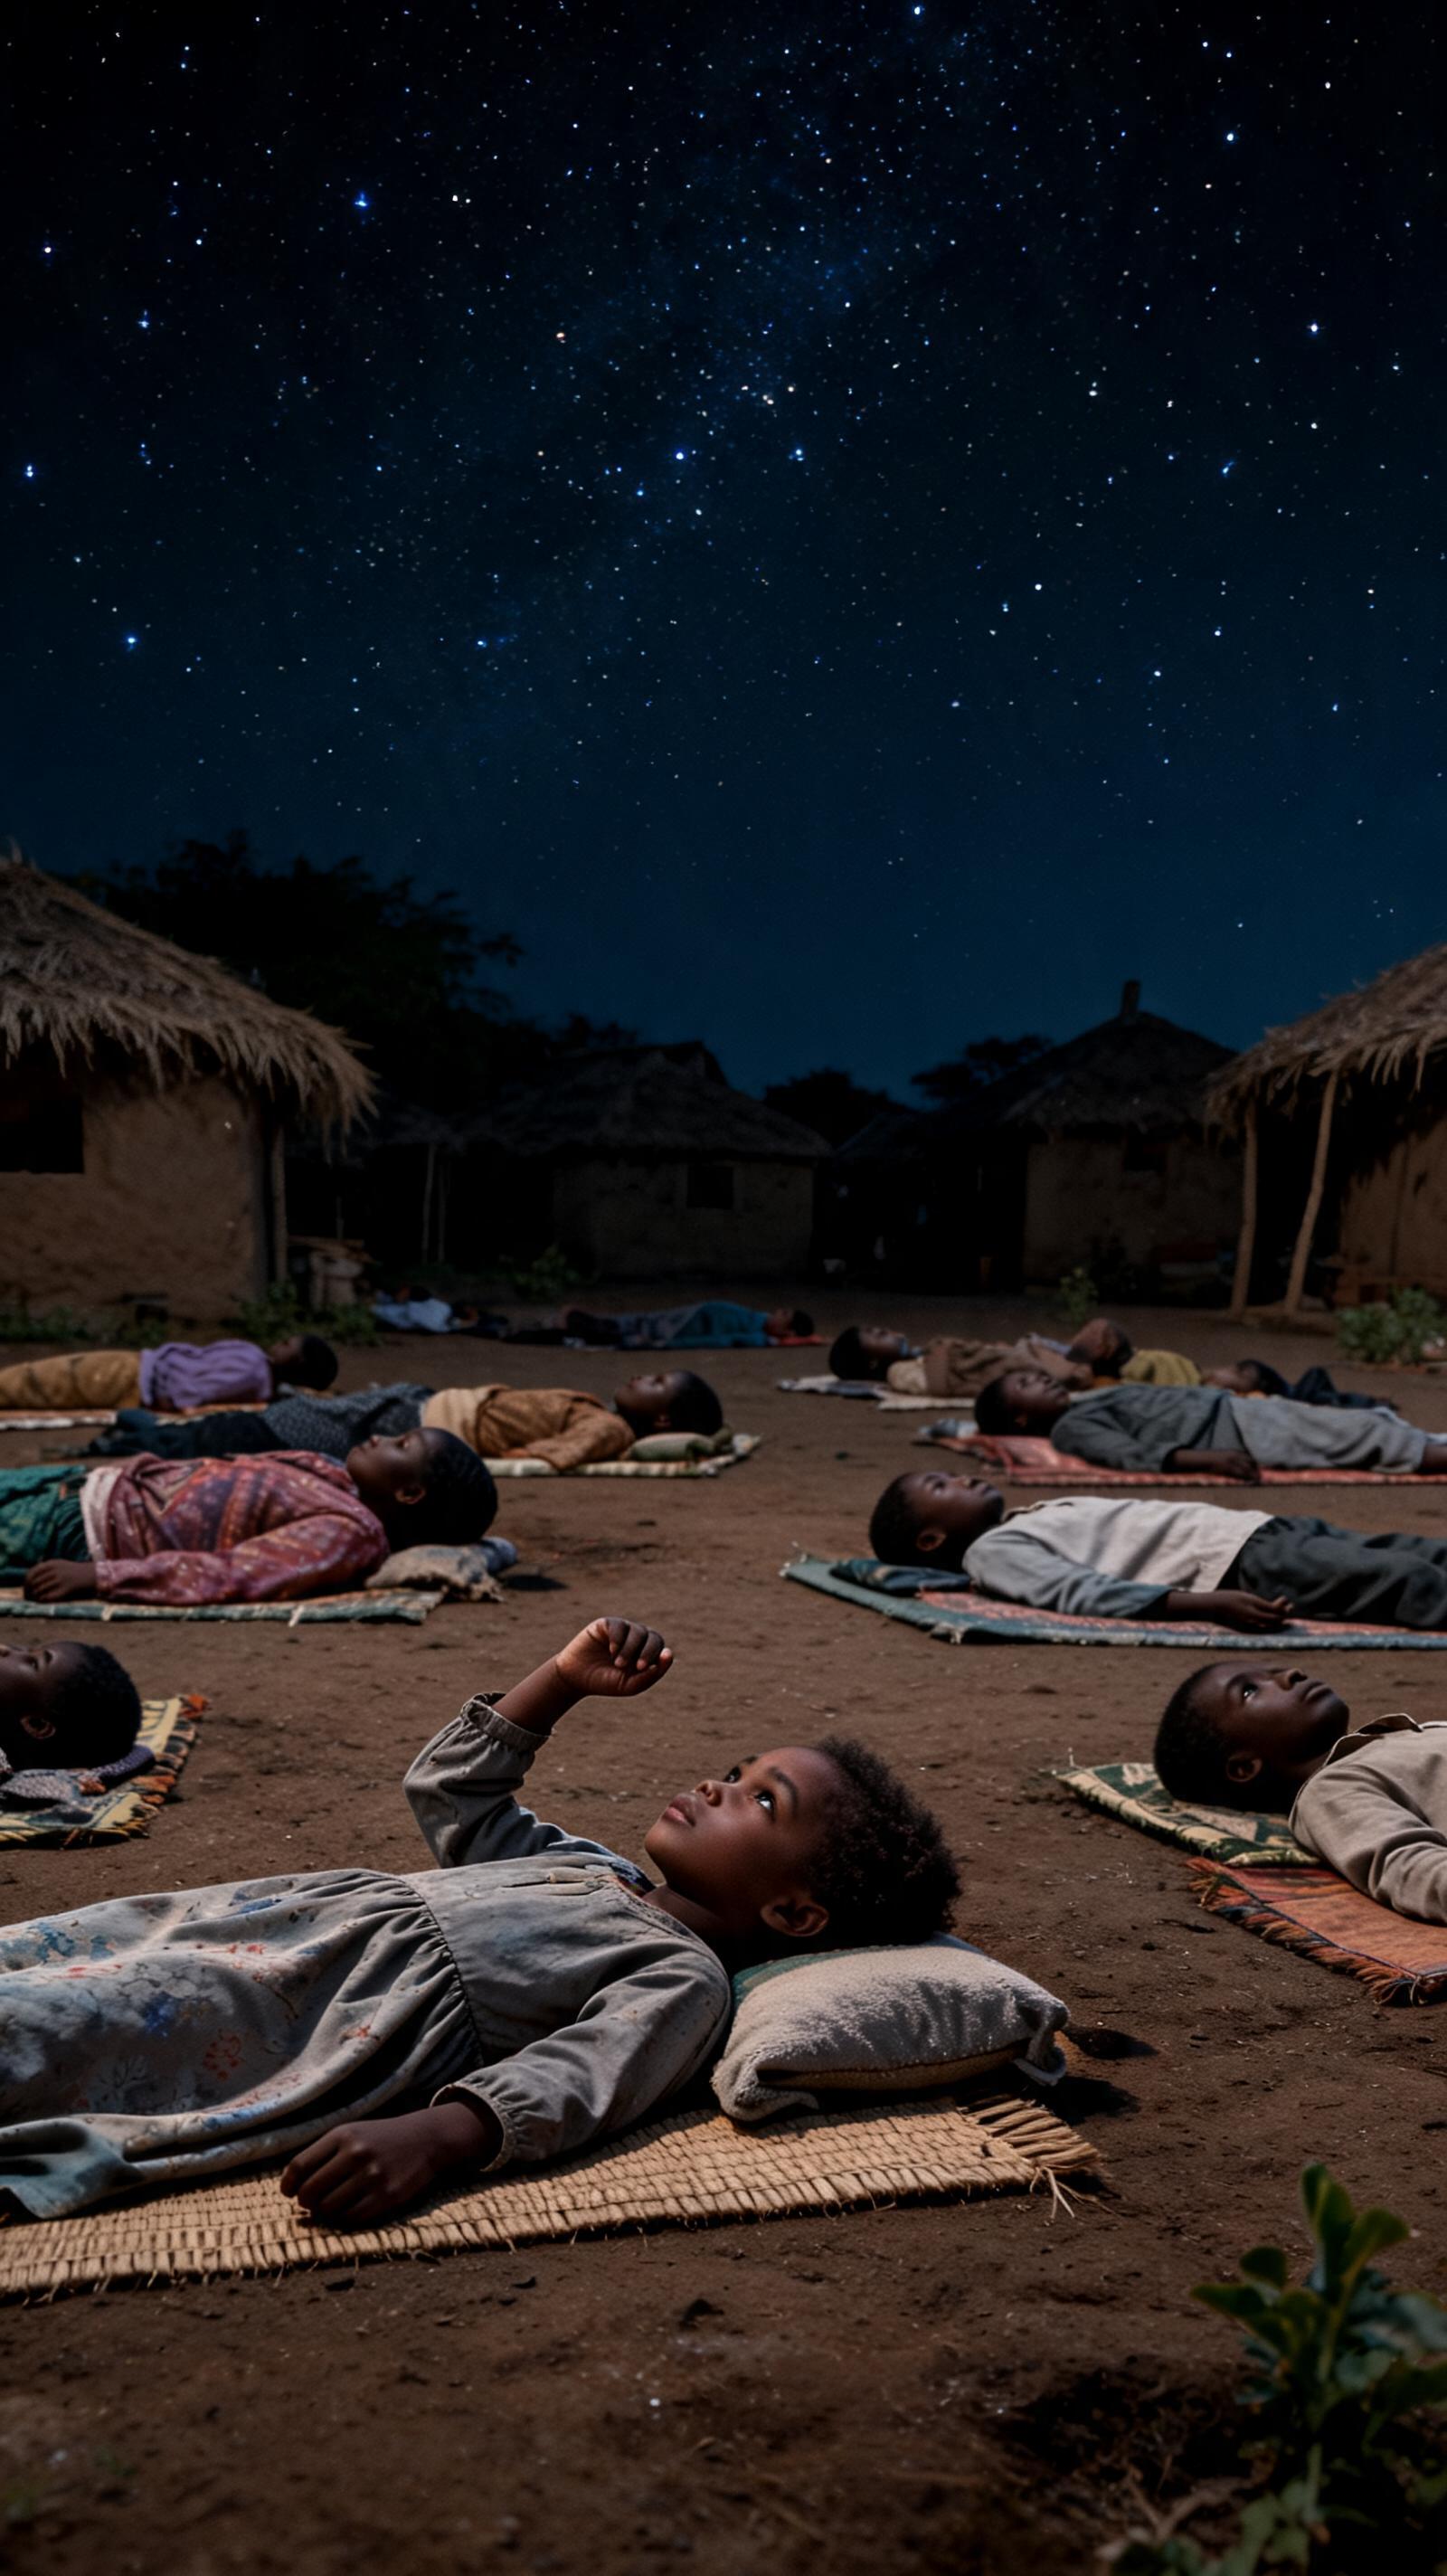
A cinematic film still, vertical 9:16, natural light, documentary realism, no text, no captions. Tanzania, 1978. The main character is a 5-year-old girl, seen in an ordinary modest village setting. Scene: The nights are too hot to sleep indoors. Everyone lies down in the yard, and you count stars...
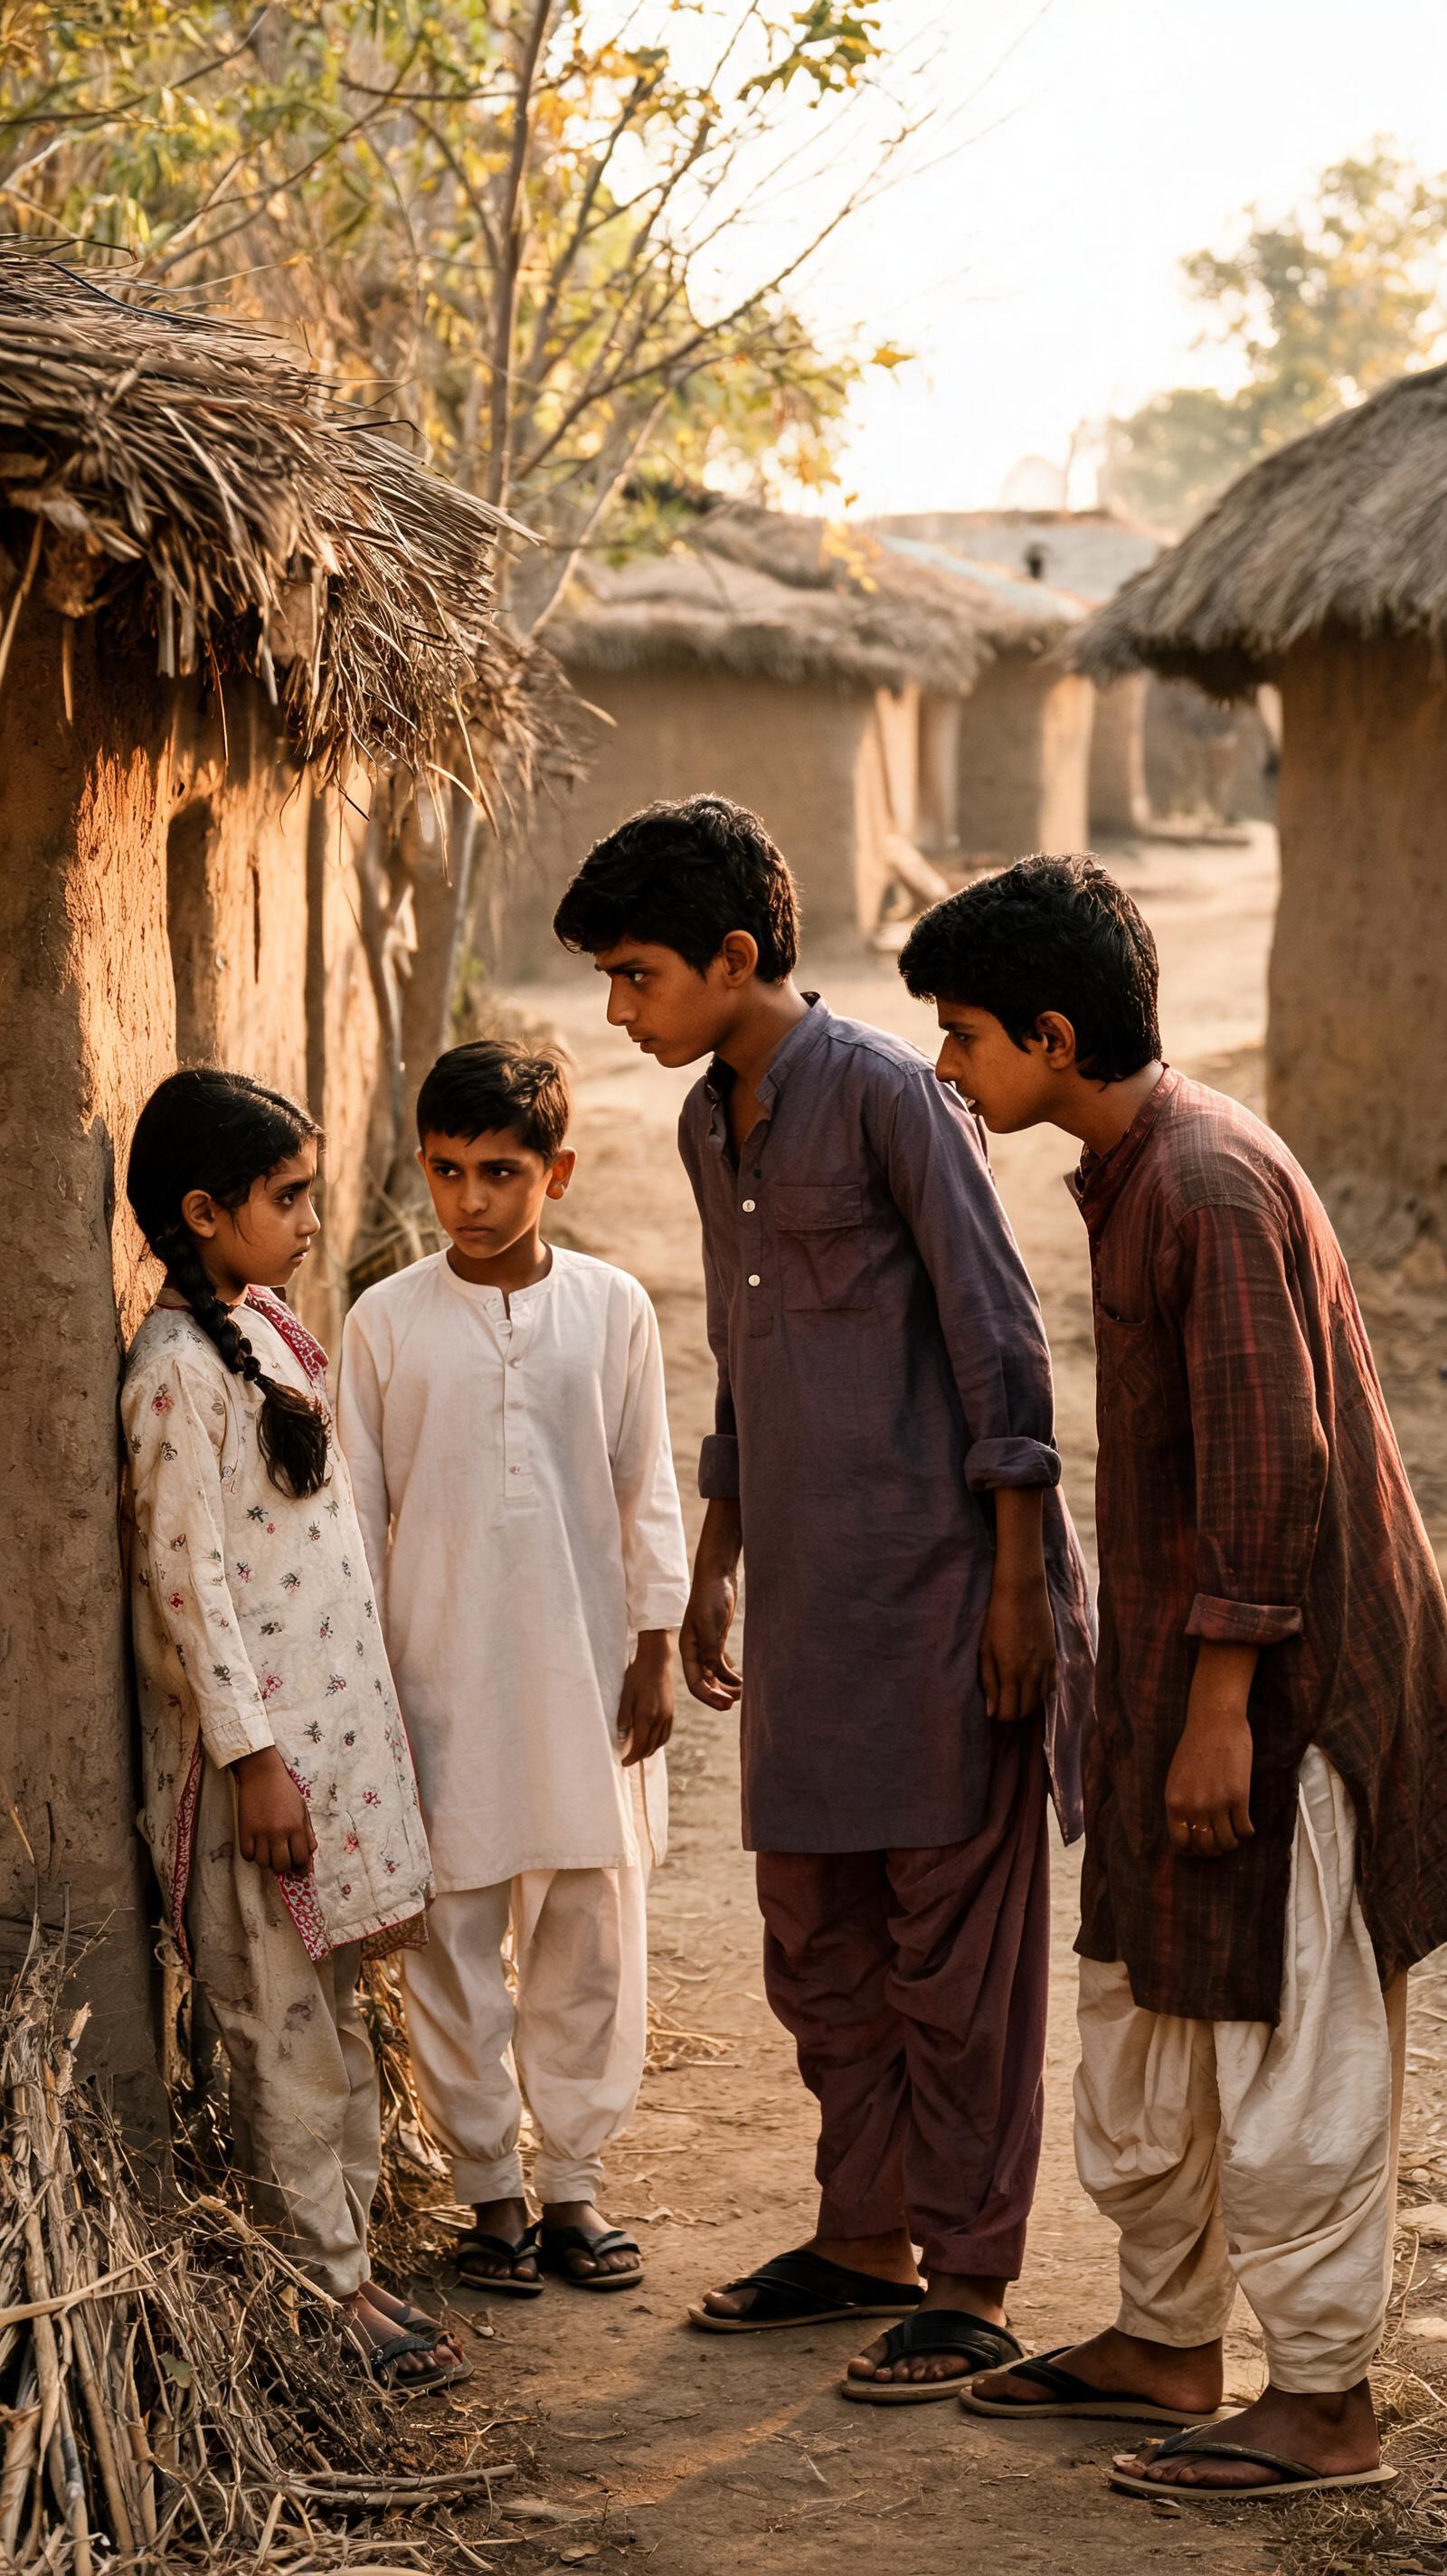
A cinematic film still, vertical 9:16, natural light, documentary realism, no text, no captions. India, 1976. The main character is a 8-year-old girl, seen in an ordinary modest village setting. Scene: Bigger children corner you behind the houses. Then Rohit is standing next to you, saying...
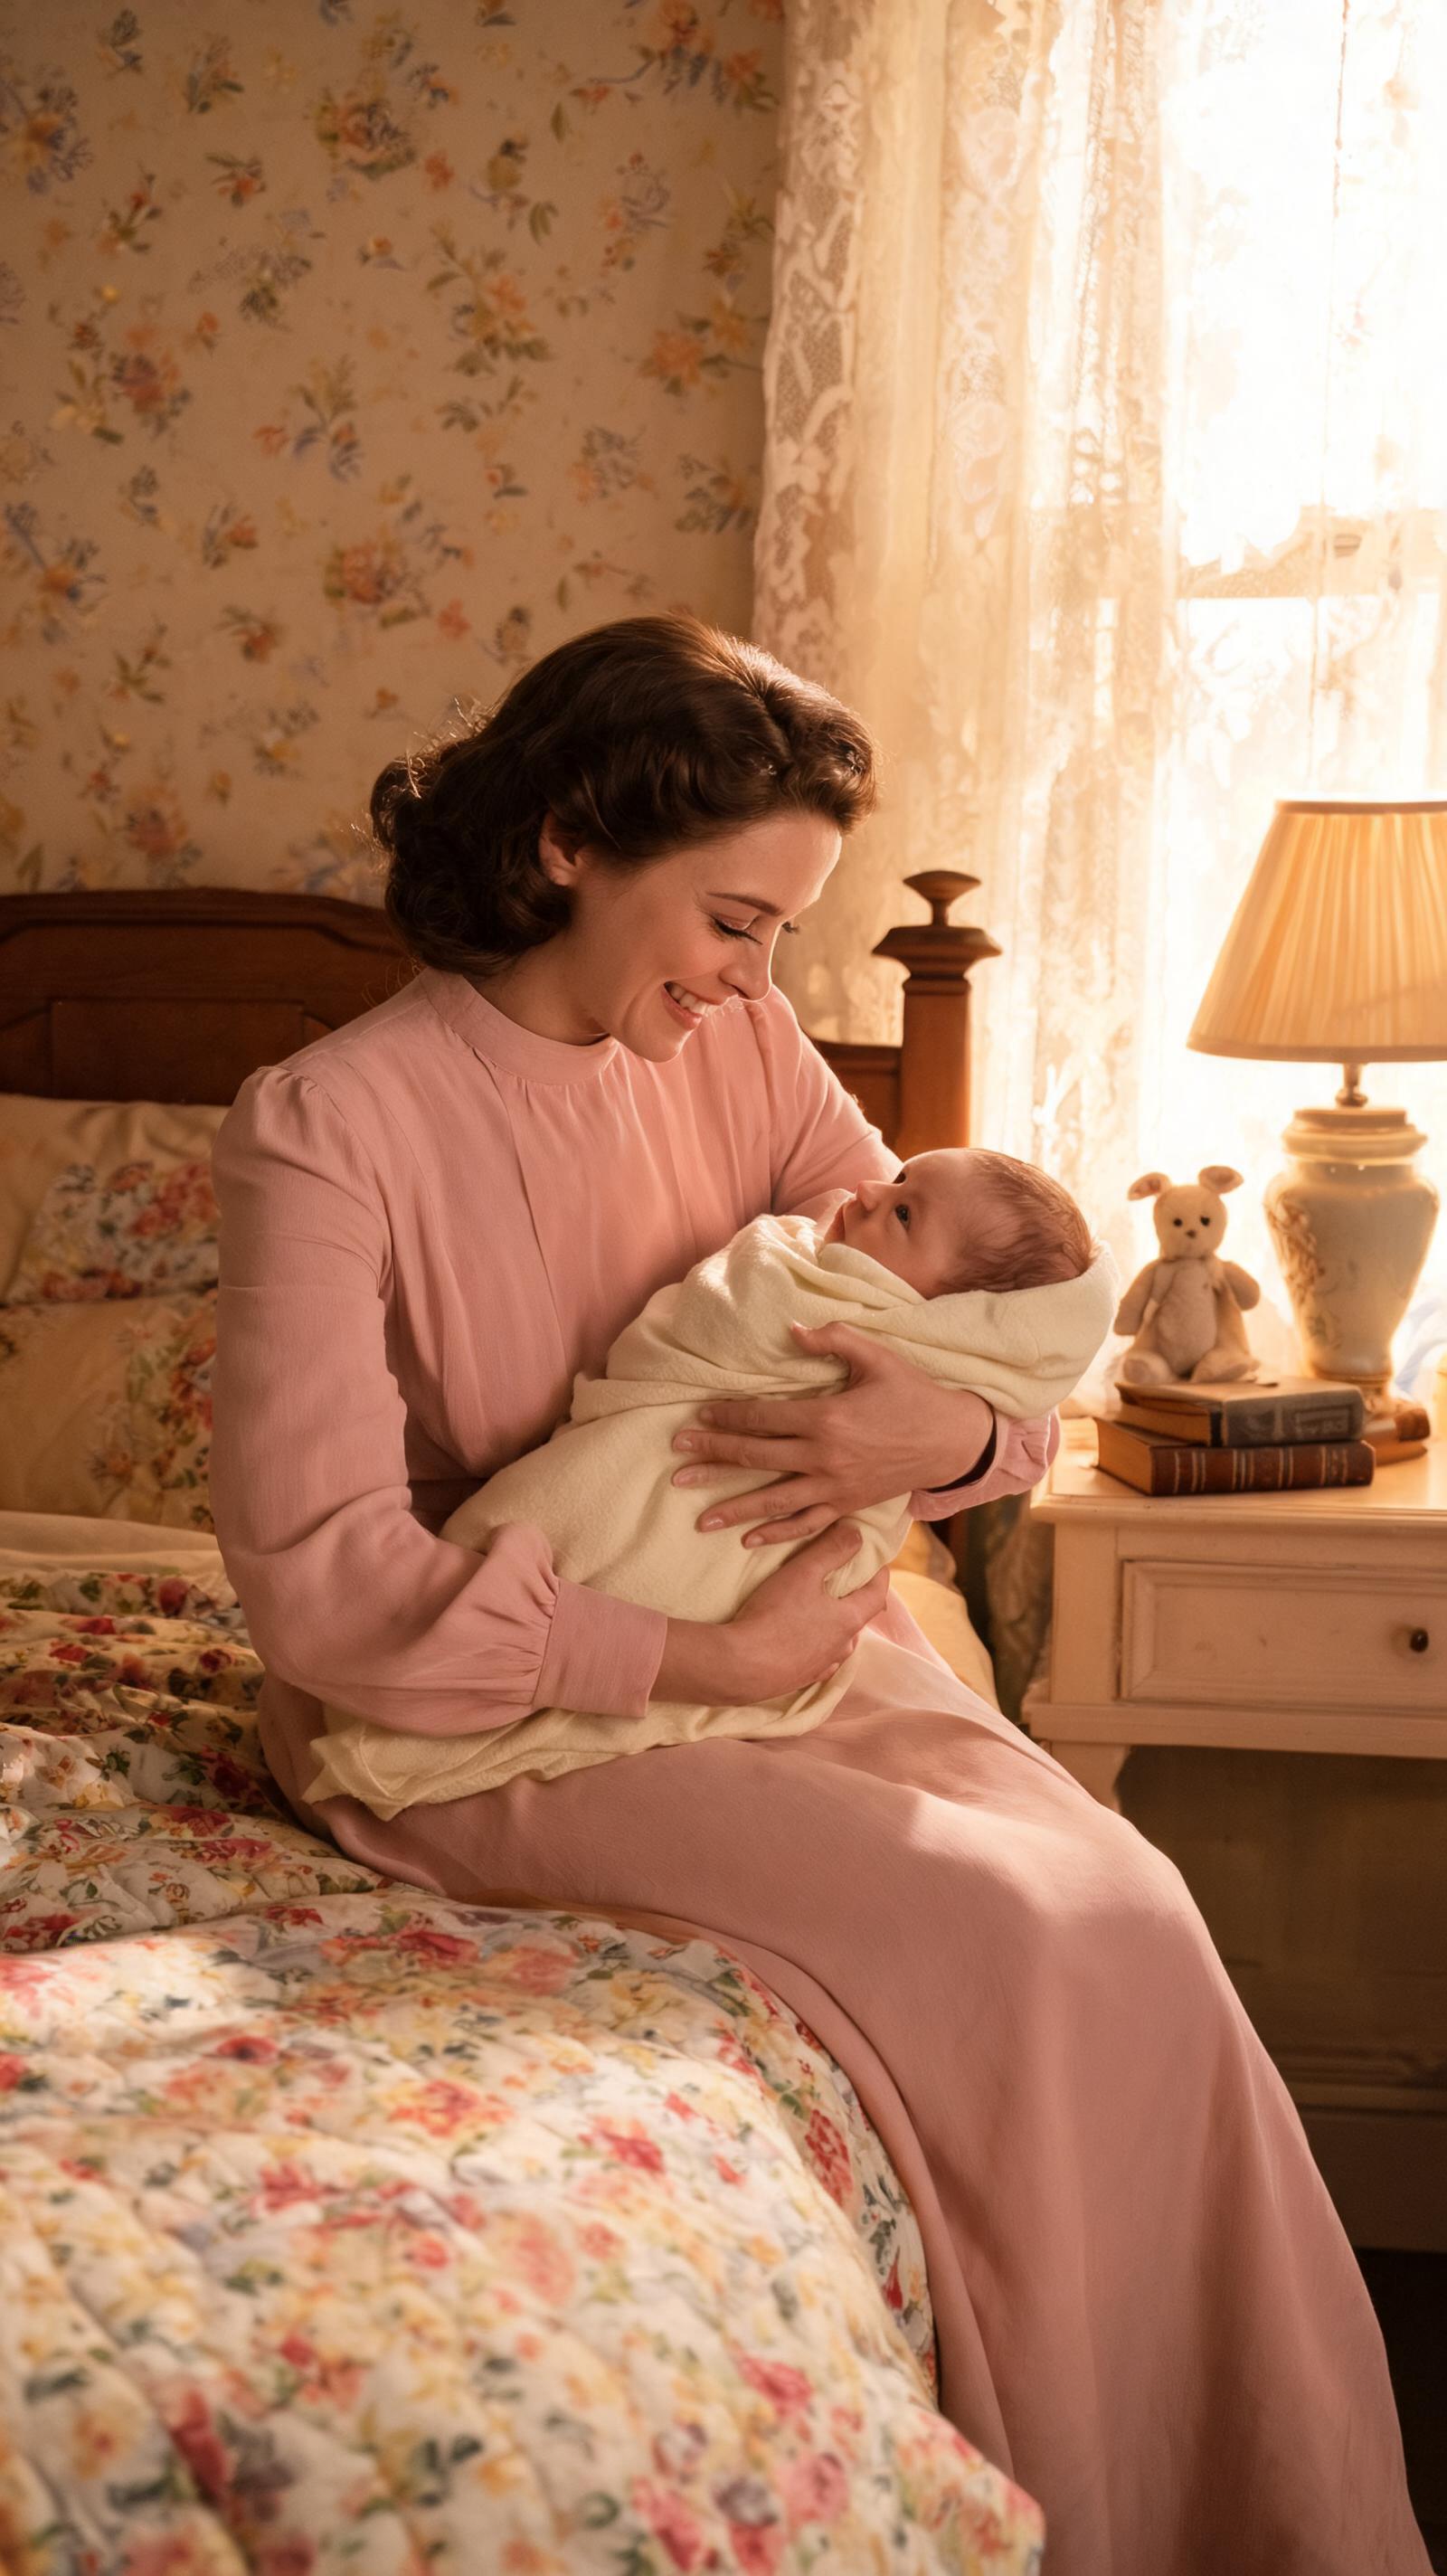
A still from a 3D animated feature film, vertical 9:16, stylised appealing characters with expressive eyes, soft warm cinematic lighting, richly detailed setting, no text, no captions. United States, 1950. The main character is a baby, seen in an ordinary well-off village setting. Scene: You are...
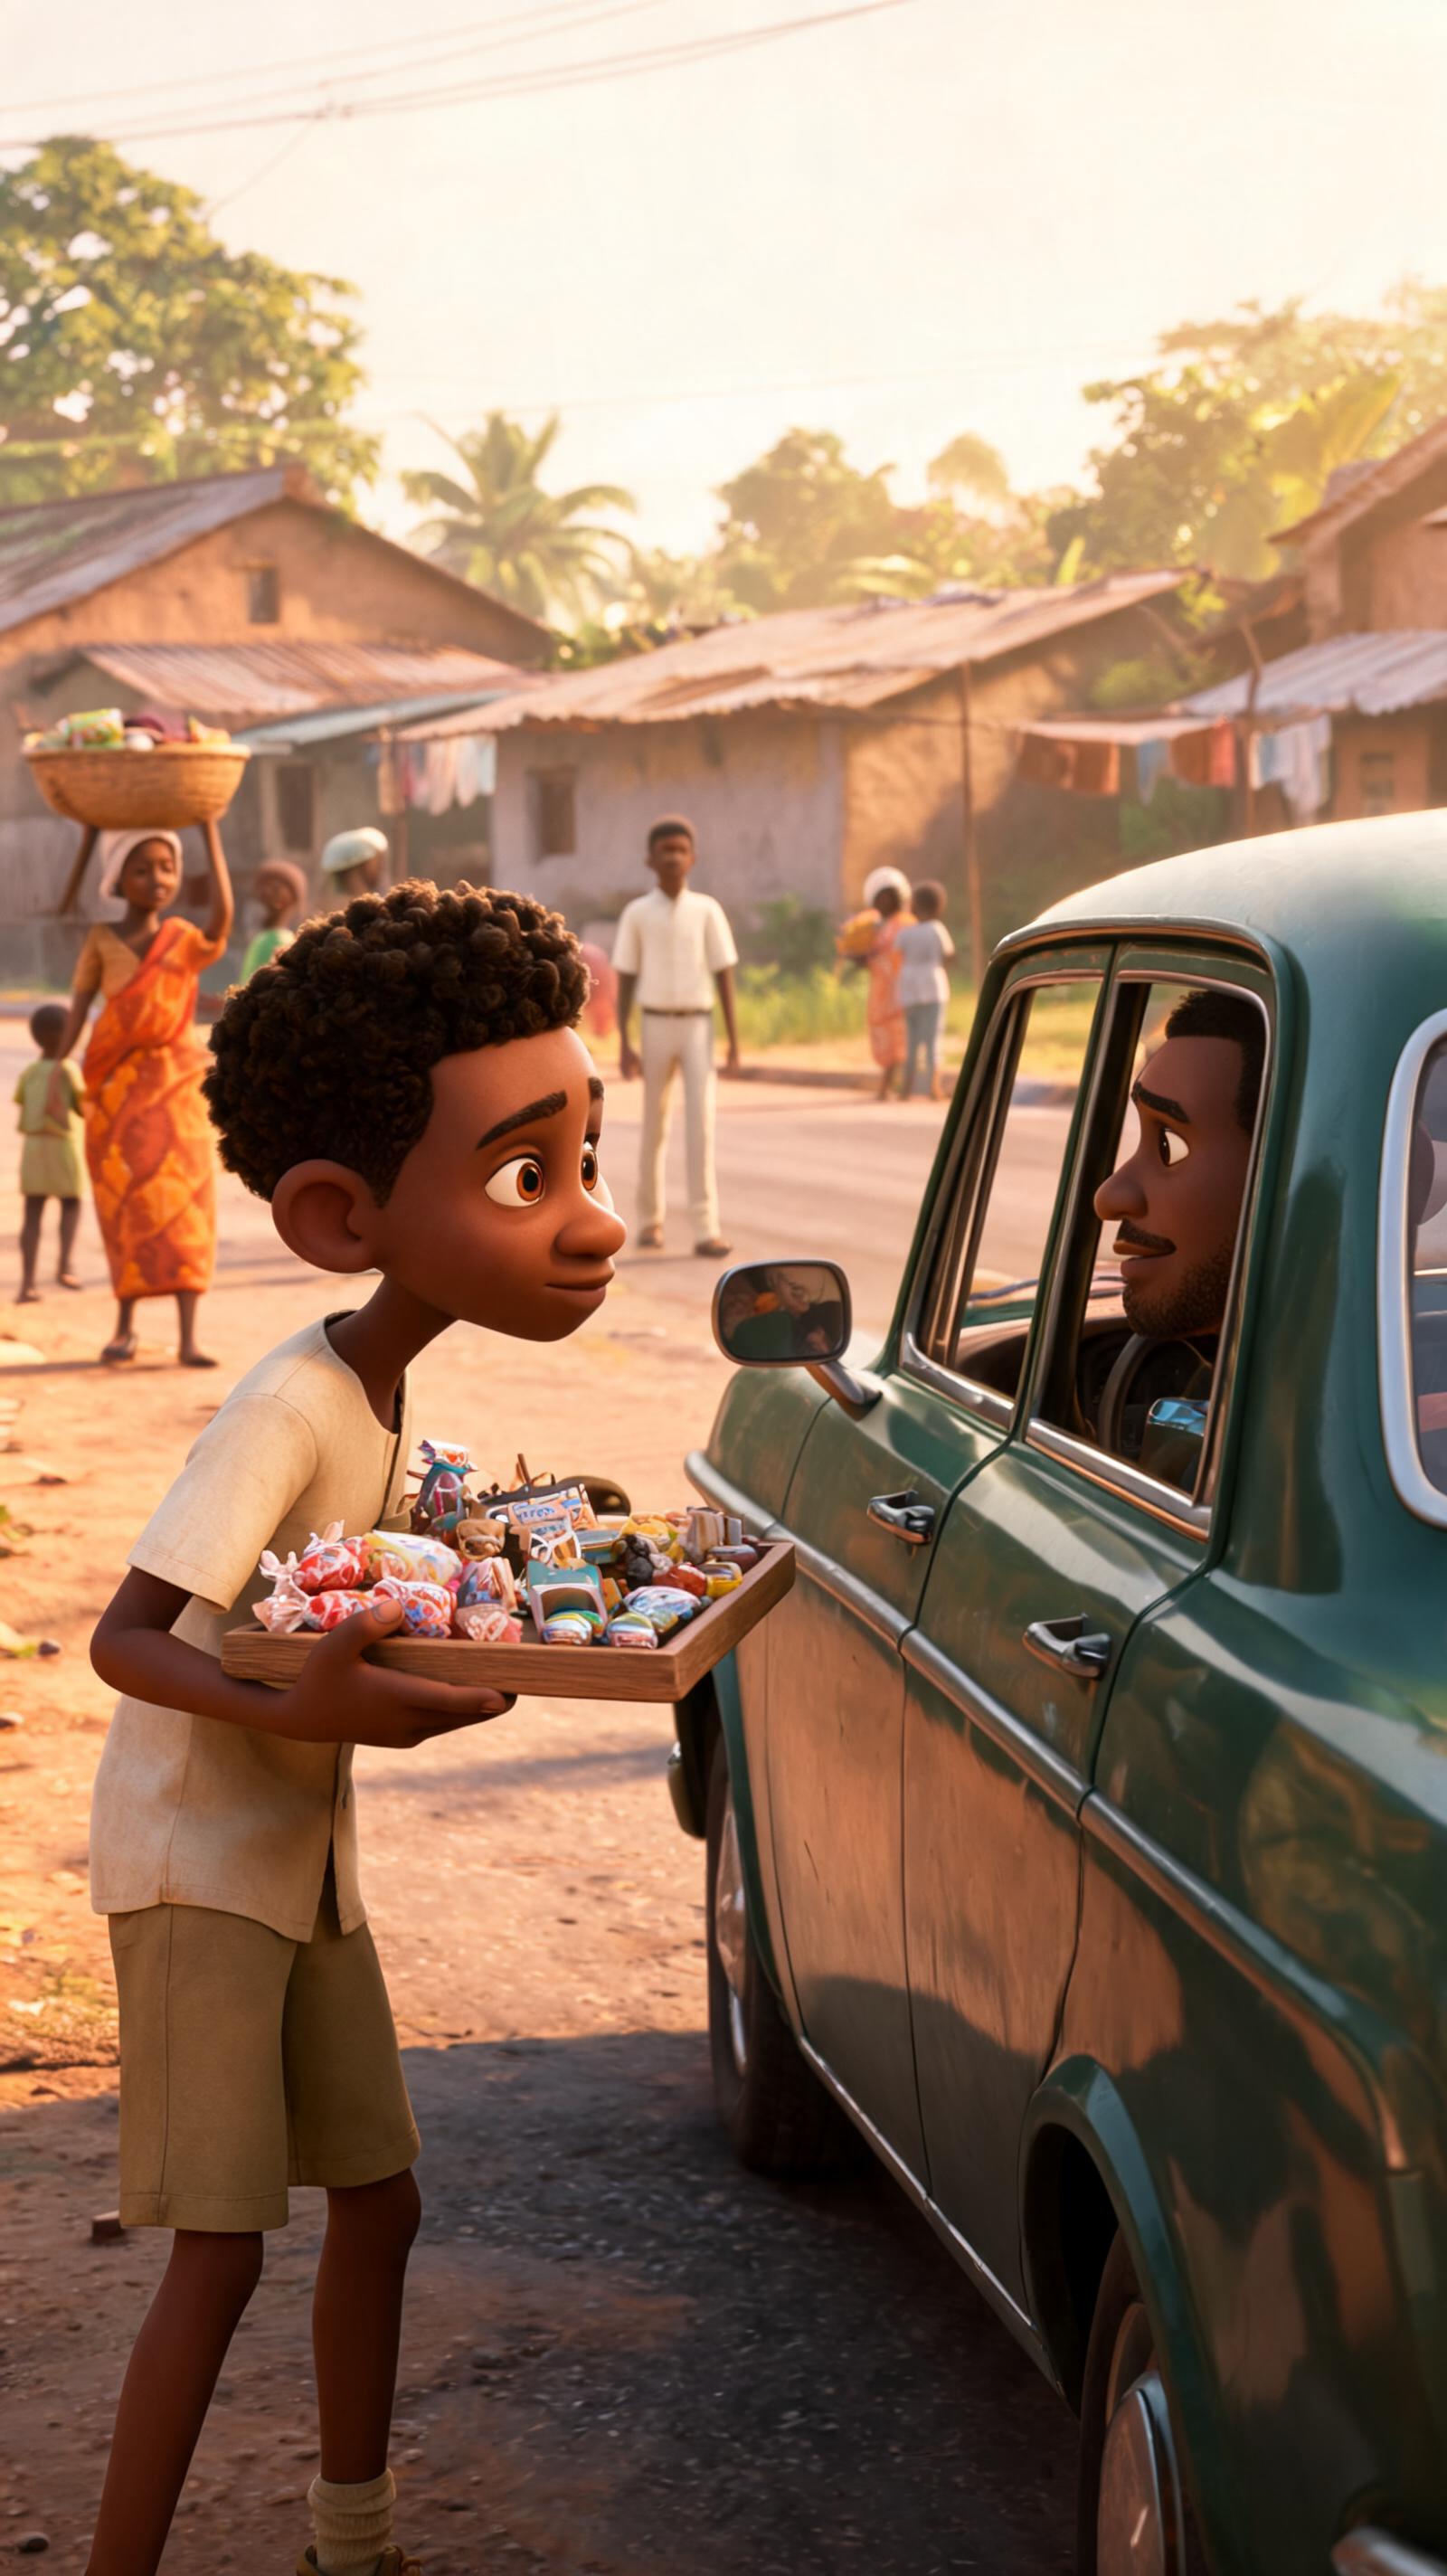
A still from a 3D animated feature film, vertical 9:16, stylised appealing characters with expressive eyes, soft warm cinematic lighting, richly detailed setting, no text, no captions. Benin City, Nigeria, 1963. The main character is a 8-year-old boy, seen in an ordinary poor city setting. Scene:...
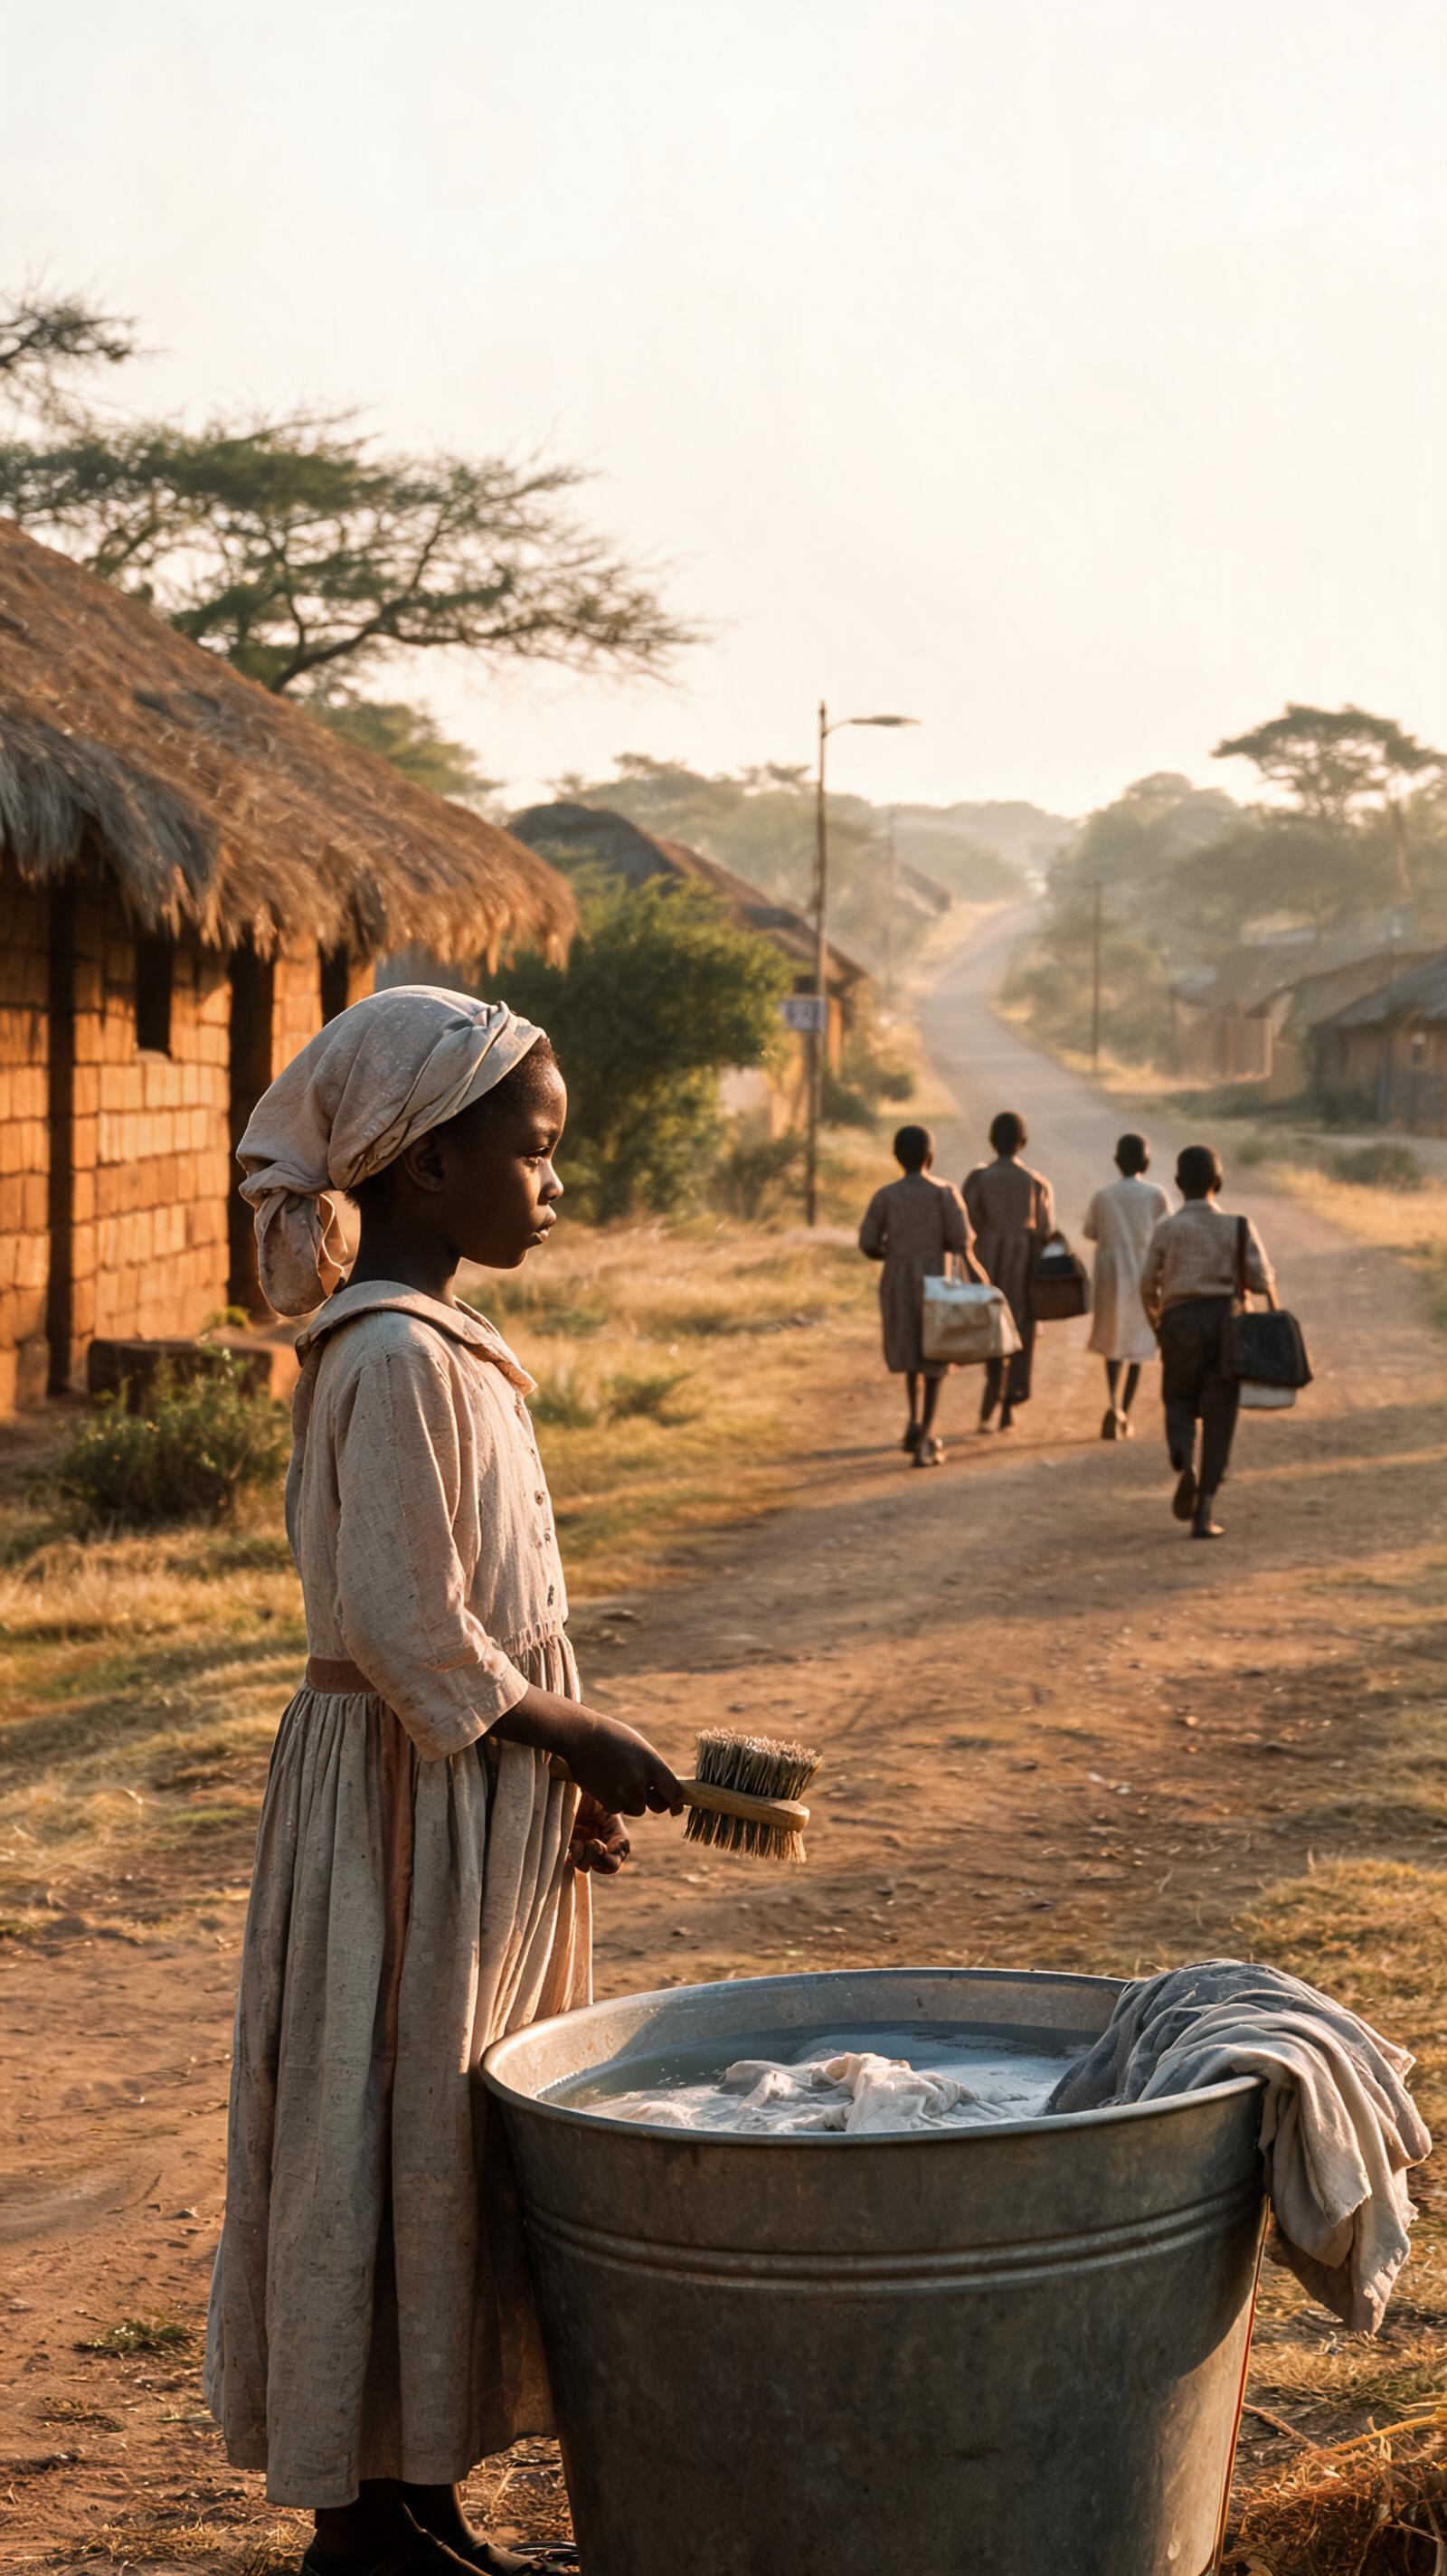
A cinematic film still, vertical 9:16, natural light, documentary realism, no text, no captions. South Africa, 1962. The main character is a 7-year-old girl, seen in an ordinary well-off village setting. Scene: In the morning other children walk past with bags. You watch them as far as the bend...
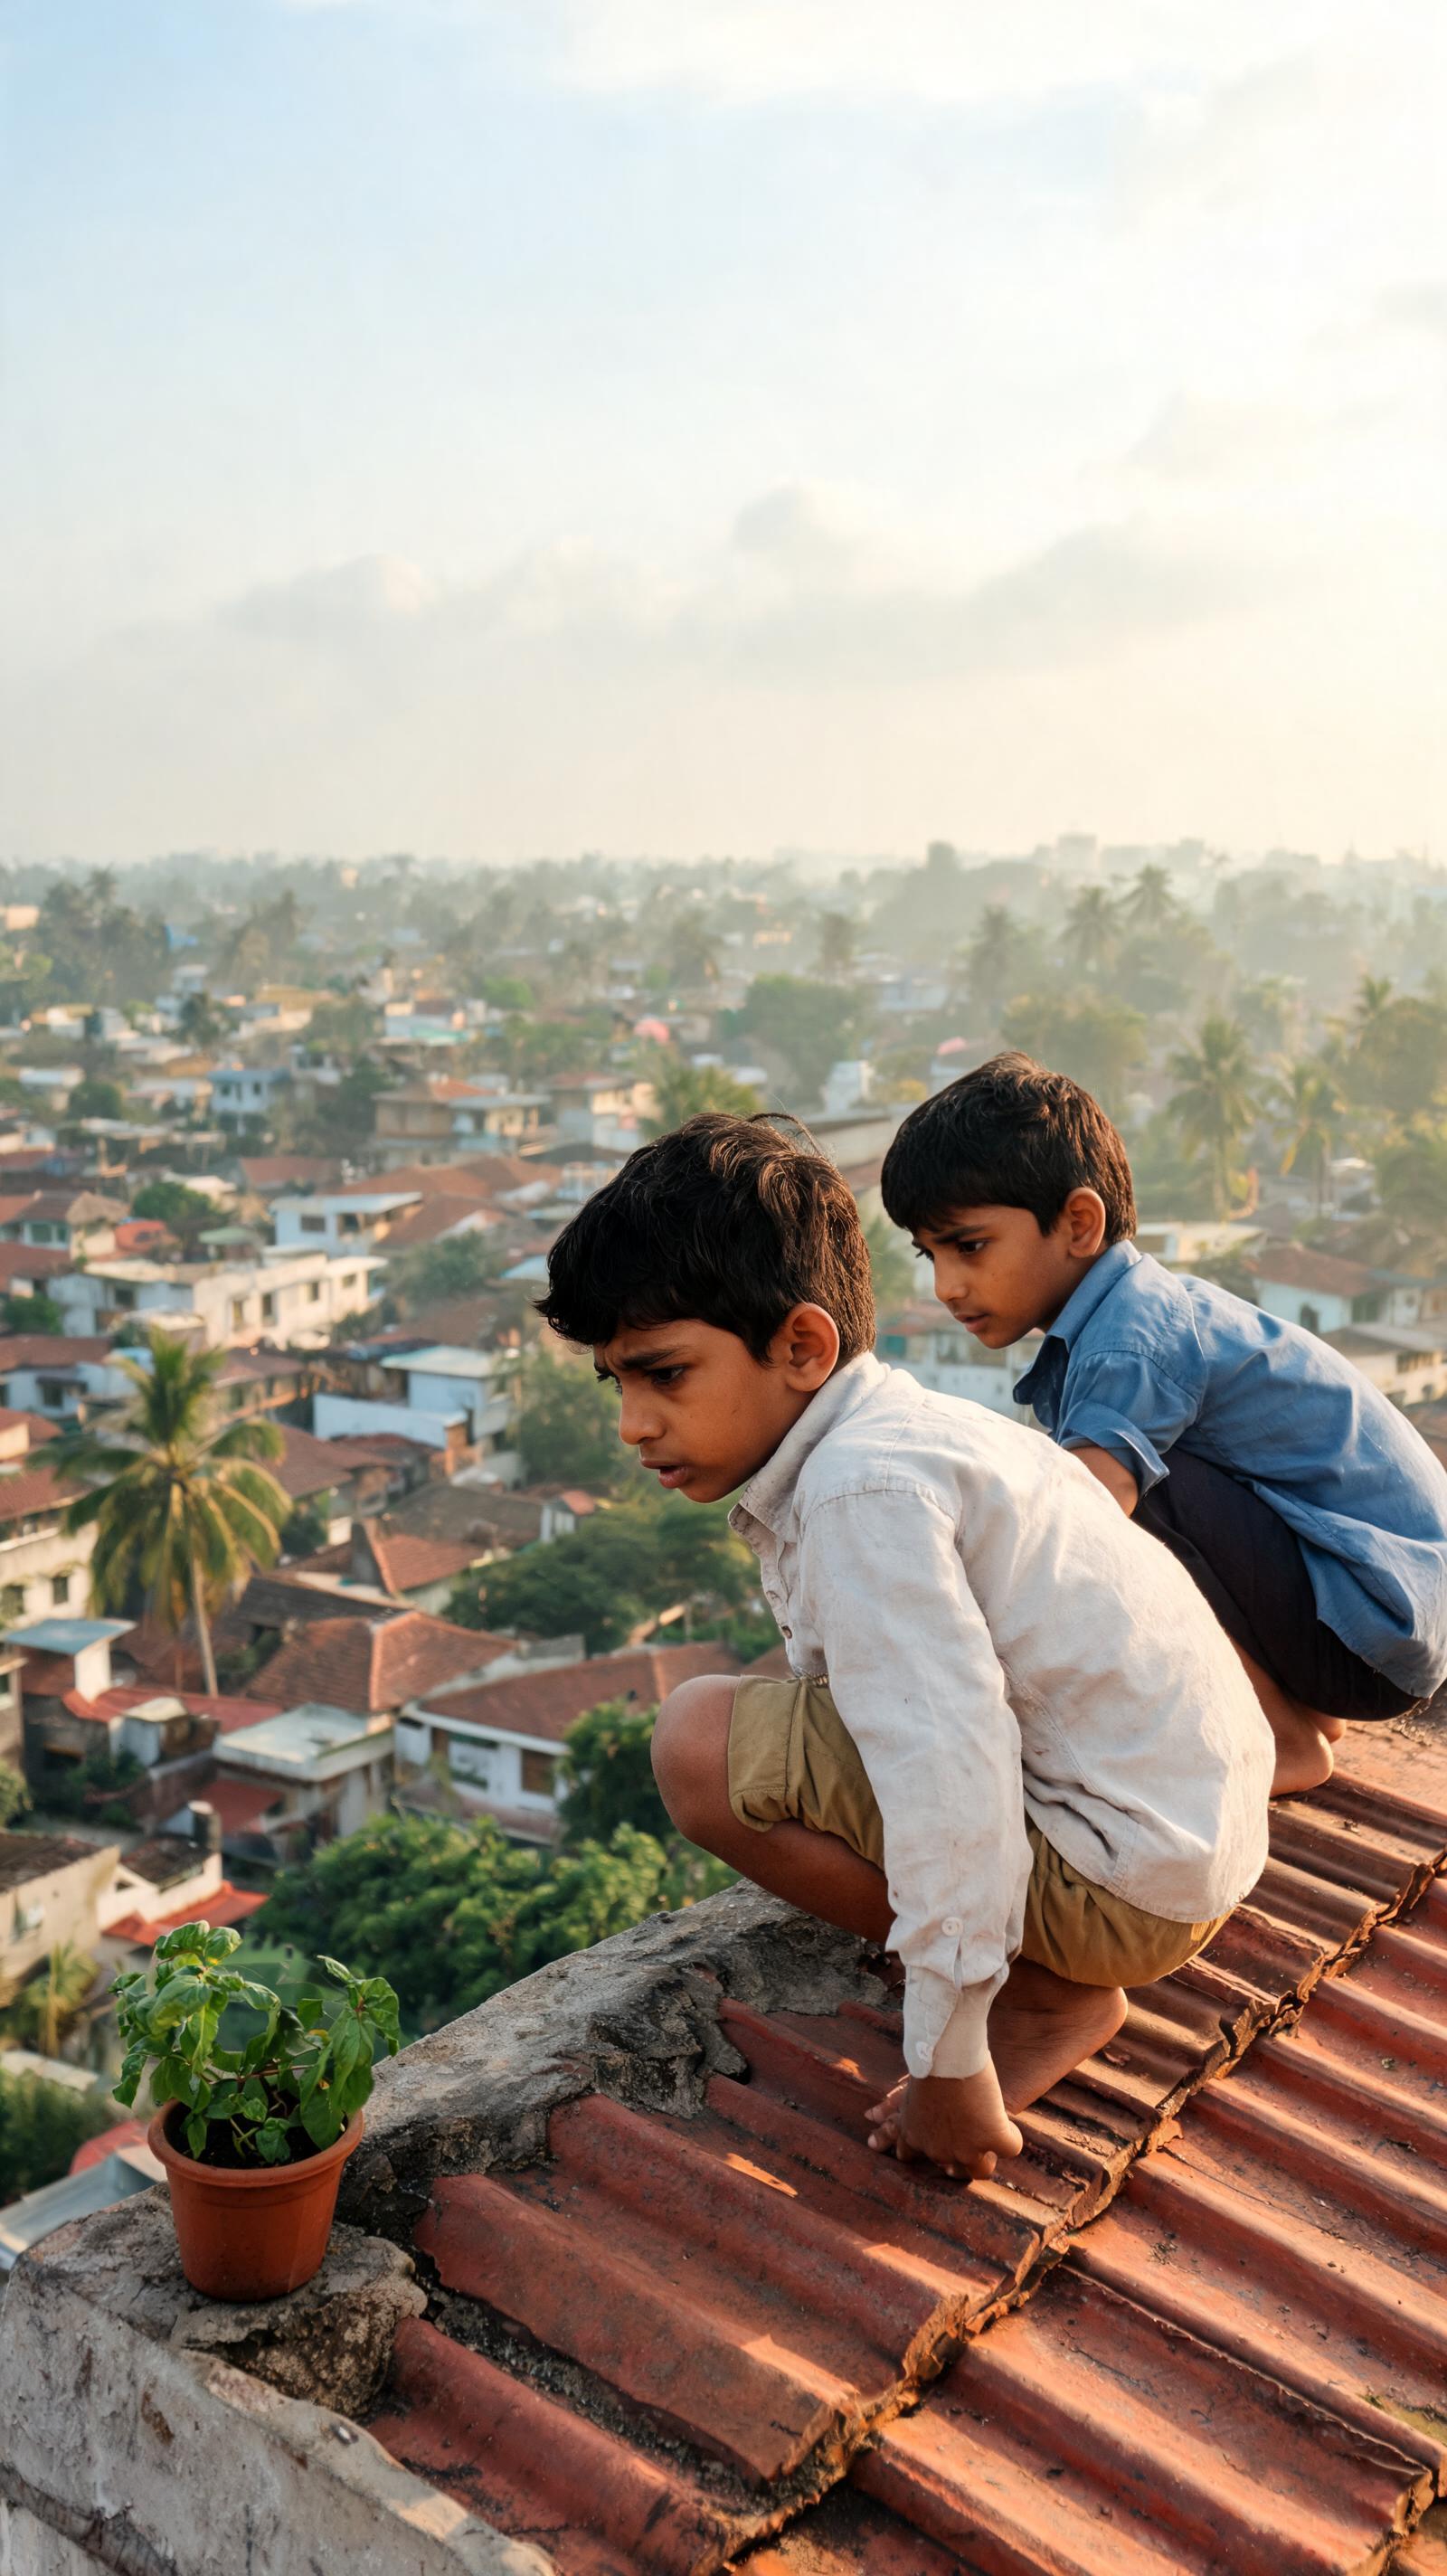
A cinematic film still, vertical 9:16, natural light, documentary realism, no text, no captions. Bengaluru, India, 1988. The main character is a 6-year-old boy, seen in an ordinary modest city setting. Scene: You climb onto a roof with a friend. Below lies the city of Bengaluru; you look for your...
Seedream 5.0 Pro produce immagini ricche e dettagliate con tipografia accurata e un forte controllo dello stile, dagli editoriali di moda al packaging e ai poster illustrati. Esegue il rendering tra 1 e 4 megapixel (il valore predefinito auto_2K sceglie un fotogramma 2K per il prompt) e può restituire fino a sei immagini per richiesta. Un miglioratore del prompt integrato viene eseguito in modalità standard o fast.
Invia il nome canonico oppure il nome nativo, non entrambi. Nomi canonici
promptobbligatorio
image_sizefacoltativo
num_imagesfacoltativo
num_outputs
output_formatfacoltativo
enhance_prompt_modefacoltativo
{
  "id": "req_8k2m4q7x1z9c3v5b6n0p2r4t",
  "object": "request",
  "model": "bytedance/seedream/v5/pro/text-to-image",
  "status": "succeeded",
  "created_at": "2026-10-20T12:00:00Z",
  "started_at": "2026-10-20T12:00:02Z",
  "completed_at": "2026-10-20T12:00:09Z",
  "queue_position": null,
  "cost": {
    "credits": 135,
    "usd": "0.135",
    "charged": 135,
    "refunded": 0
  },
  "input": {
    "prompt": "Fashion editorial of a model in a coat patterned with West African textile motifs, studio backdrop, soft key light",
    "image_size": "auto_2K"
  },
  "output": {
    "images": [
      {
        "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
        "content_type": "image/jpeg",
        "file_name": "0-output.jpeg",
        "file_size": 1843200,
        "width": 1024,
        "height": 768
      }
    ]
  },
  "outputs": [
    {
      "type": "image",
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
      "content_type": "image/jpeg",
      "file_size": 1843200,
      "width": 1024,
      "height": 768,
      "stored": true
    }
  ],
  "error": null,
  "metrics": {
    "inference_seconds": 6.8
  },
  "urls": {
    "self": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t",
    "cancel": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t/cancel"
  }
}
Per gli agenti AI: questa pagina in Markdown è disponibile all'indirizzo https://doitong.com/it/developers/models/bytedance/seedream/v5/pro/text-to-image.md. Tutti i modelli e le guide: https://doitong.com/developers/llms.txt